Text-to-SQL: From Natural Language to Reliable Queries
A practical guide to building reliable text-to-SQL systems: architectures, prompts, schema linking, safety, evaluation, and production tips.
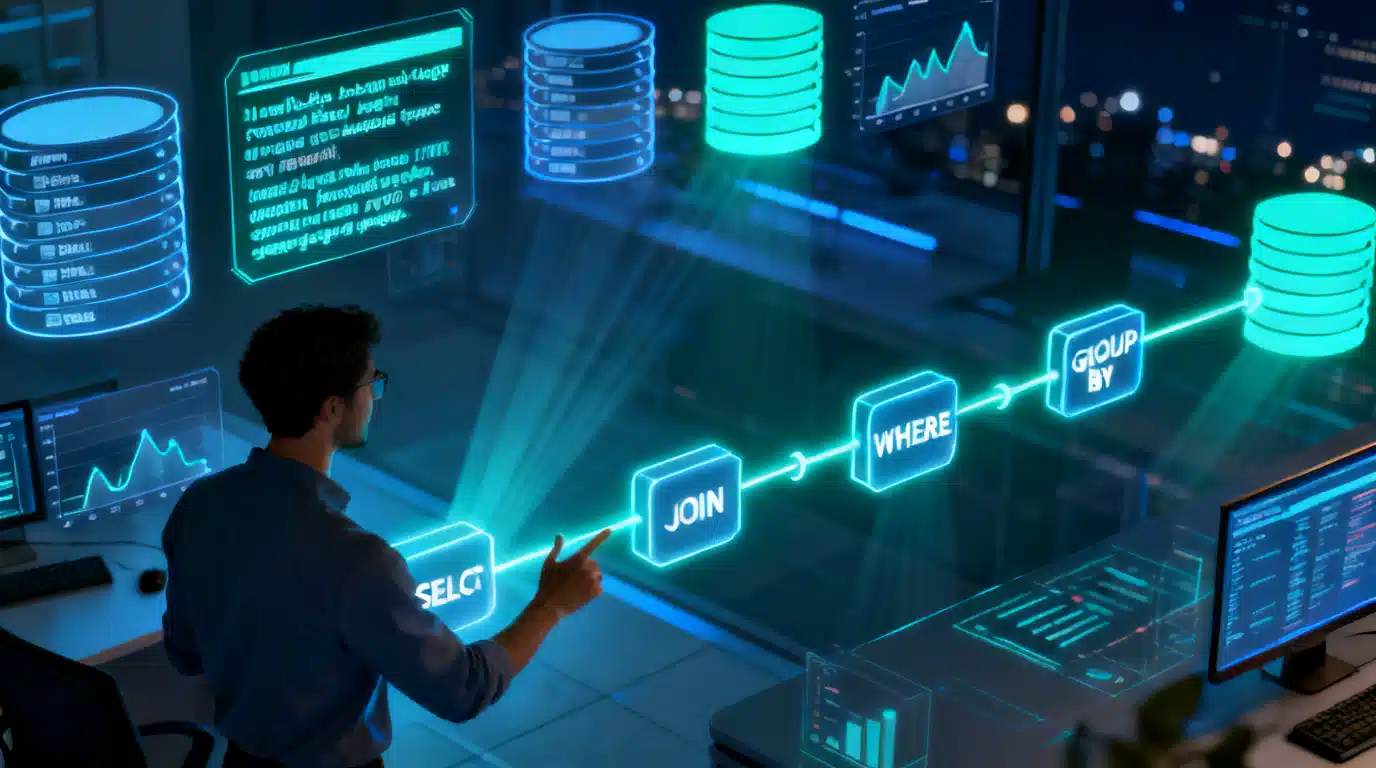
Image used for representation purposes only.
Why Text-to-SQL Matters
Natural language access to data removes the last mile between business questions and analytical answers. Instead of waiting on dashboards or writing queries by hand, anyone can ask, “What were last quarter’s cancellations by region?” and get a precise SQL statement—and result—back. Done well, text-to-SQL increases data reach, reduces analyst bottlenecks, and standardizes logic. Done poorly, it creates ambiguity, cost overruns, and risky queries. This guide explains how to build reliable, secure, and accurate text-to-SQL systems from first principles.
What Makes Text-to-SQL Hard
Translating language to SQL is more than pattern matching:
- Ambiguity: “sales” could mean gross, net, invoice sum, or revenue after refunds.
- Schema complexity: Real schemas contain dozens of tables, foreign keys, synonyms, and legacy naming.
- SQL dialects: Postgres, BigQuery, Snowflake, and SQL Server differ in functions, quoting, and date math.
- Safety: Open-ended generation can issue expensive scans or even DDL/DML if not constrained.
- Evaluation: Two syntactically different queries can return the same answer—or the same SQL can behave differently across warehouses.
An End-to-End Pipeline
A production-grade system typically follows this loop:
- Input understanding
- Normalize the question; detect intent, metrics, time windows, filters, and sort/limit.
- Context construction
- Retrieve the smallest relevant slice of the schema (tables, columns, PK/FK, column descriptions, synonyms, sample values).
- Candidate generation
- Produce one or more SQL candidates using rules, models, or LLMs with constraints.
- Validation and ranking
- Enforce safety policies, run a static checker, optionally dry-run/EXPLAIN, and rank by likelihood + cost + semantics.
- Result presentation and repair
- Execute in a read-only environment; show results plus the SQL; allow quick reformulation (“exclude test users”).
- Feedback capture
- Log question, chosen SQL, execution stats, user satisfaction; use for continuous improvement.
A Compact Example
Schema (simplified):
- customers(id, name, city)
- orders(id, customer_id, order_date, total)
- order_items(id, order_id, product_id, quantity, unit_price)
- products(id, category, name)
User question: “Top 5 cities by revenue in 2025.”
Candidate SQL:
SELECT c.city, SUM(oi.quantity * oi.unit_price) AS revenue
FROM orders o
JOIN order_items oi ON oi.order_id = o.id
JOIN customers c ON c.id = o.customer_id
WHERE o.order_date >= '2025-01-01' AND o.order_date < '2026-01-01'
GROUP BY c.city
ORDER BY revenue DESC
LIMIT 5;
Key steps the system performed:
- Linked “revenue” → aggregation over order_items.quantity * unit_price (business metric).
- Identified join path customers → orders → order_items.
- Interpreted “in 2025” as a closed-open date range.
- Added ranking and limit.
Core Design Choices
There are three dominant architectural patterns. Many robust systems blend them.
- Rule- and grammar-based
- Approach: Define a SQL grammar and hand-crafted templates.
- Pros: Deterministic, safe, low compute cost; excellent for narrow domains.
- Cons: Brittle with paraphrases; expensive to maintain as schemas evolve.
- Neural semantic parsers
- Approach: Train encoder–decoder models that map questions and schemas to SQL; integrate schema linking and constrained decoding.
- Pros: Strong accuracy on known domains; can generalize within similar schemas.
- Cons: Requires labeled data; struggles with truly novel schemas and edge idioms.
- LLM + tool hybrid
- Approach: Use an LLM for reasoning and composition, but constrain with:
- A formal SQL grammar or abstract syntax tree (AST) decoder.
- Schema-aware retrieval and join path search.
- Execution feedback (dry-run, error repair, cost-based pruning).
- Pros: Fast to deploy; flexible phrasing; strong zero/low-shot performance.
- Cons: Needs careful guardrails to control cost, latency, and safety.
Schema Linking: From Words to Columns
Correct joins and filters hinge on precise schema grounding.
Techniques:
- Name and description matching: Token/character similarity plus stemming and acronym handling.
- Synonym tables: Map business terms (e.g., “GMV”, “churned user”) to column expressions or CTEs.
- Embedding retrieval: Represent columns, tables, and sample values as vectors; retrieve likely matches from the question.
- Join graph search: Build a graph from PK/FK metadata; find minimal join paths between referenced tables, penalizing fan-out.
- Value probing: Sample column values to confirm candidate matches (“city” should look like location names).
Generating SQL Reliably
Even the smartest model benefits from structure.
- Query sketches: Fill a high-level template: SELECT-AGGREGATES, FROM-JOINS, WHERE, GROUP BY, HAVING, ORDER BY, LIMIT.
- Constrained decoding: Enforce a SQL grammar/AST so only legal tokens or nodes are emitted.
- Function whitelists: Allow only safe scalar functions and vetted UDFs; forbid DDL/DML.
- Dialect adapters: Normalize to a logical SQL and render to the target dialect for date math, string functions, and quoting.
- Deterministic literals: Standardize time windows (“last month”), booleans, and null handling to avoid flaky results.
Prompting Patterns That Work
When using an LLM, the prompt is your interface contract.
- Serialize the schema narrowly:
- Include only relevant tables/columns, PK/FK notes, and column descriptions.
- Provide metric definitions as named snippets.
- Give few-shot examples that mirror your domain.
- Ask for a single final SQL block and nothing else; request comments only if useful for auditing.
- Add guardrails in the instruction: “Use only tables shown; never modify data; keep to one query; default to closed-open date ranges.”
- Provide a test harness: If EXPLAIN or dry-run fails, ask the model to repair using the error string, but keep the same constraints.
Minimal example prompt sketch:
System: You are a SQL generator. Produce one safe, read-only query.
Context: Tables, columns, PK/FK, metric definitions.
User: Natural language question.
Rules: Allowed functions; restrict to given tables; use closed-open dates; limit 100 unless asked.
Output: SQL only.
Safety, Governance, and Cost Controls
Security is non-negotiable.
- Read-only roles: Route all execution through a database role without DDL/DML permissions.
- Policy enforcement:
- Column and row-level security for PII and sensitive segments.
- Query rewrite layer to apply mandatory filters (e.g., tenant_id scoping).
- Injection resistance: Do not splice user text directly into SQL; generate from structured plans; parameterize literals.
- Static analysis: Block cross joins on wide tables, wildcard SELECT on large schemas, and unbounded scans.
- Resource quotas: Set timeouts, max bytes scanned, and concurrency caps; pre-check with EXPLAIN when possible.
- Auditing: Log the natural question, final SQL, execution stats, and who ran it.
Evaluation: From Offline to Online
You need multiple lenses to judge quality.
Offline metrics:
- Exact set match: Compare the predicted SQL’s normalized structure to ground truth; tolerant of formatting.
- Execution accuracy: Compare result sets (or hashes) within tolerances.
- Component F1: Measure correct selections of tables, joins, columns, predicates, and aggregations.
- Robustness tests: Paraphrase questions, inject noise (“typo”, “synonyms”), and perturb schemas (column reordering, aliasing).
Human review:
- Analysts score samples on semantic correctness, cost reasonableness, and clarity of assumptions.
Online metrics:
- Task success rate: Did the user accept the result without manual edits?
- Iteration depth: Number of reformulations to reach acceptance.
- Time to answer: End-to-end latency including model time and database execution.
- Safety incidents: Blocked queries, policy violations, or timeouts.
Building a Domain Metric Layer
Ambiguity often stems from missing business semantics. A metric layer formalizes them.
- Define canonical metrics (e.g., revenue, active users, churn) as SQL snippets or views with clear dimensions and filters.
- Give each metric a name, owner, and test suite.
- Teach the text-to-SQL system to reference metric definitions instead of inlining ad-hoc logic.
- Version the layer so historical queries remain reproducible.
Candidate Generation and Re-ranking
To balance accuracy and latency:
- Produce N diverse candidates (different join paths, metric interpretations).
- Score them with a blend of:
- Textual alignment to the question.
- Schema plausibility (FK-conforming joins, minimal fan-out).
- Cost heuristics (cardinality estimates, index usage).
- Execution feedback (dry-run status, limited sample execution).
- Return the top candidate or show two labeled options when ambiguity is high.
A Simple Implementation Sketch
Here is high-level pseudocode for a hybrid system:
function answer(question):
  intent = parse_intent(question)
  context = retrieve_schema_slice(intent)
  synonyms = lookup_synonyms(intent)

  candidates = generate_sql_candidates(
    question, context, synonyms,
    grammar=sql_ast, n=4
  )

  scored = []
  for sql in candidates:
    if violates_policies(sql): continue
    explain = dry_run(sql)
    if explain.error:
      sql = repair_with_error(sql, explain.error, context)
    score = rank(sql, intent, context, explain.cost)
    scored.append((sql, score))

  best = argmax(scored)
  return execute_read_only(best.sql)
Handling Ambiguity and Conversation
Not every question is resolvable in one shot.
- Clarifying questions: Ask targeted follow-ups when multiple metrics or dimensions match. Example: “By ‘sales’, do you mean gross merchandise value or net revenue after refunds?”
- Multi-turn memory: Preserve chosen meanings and filters within a session; allow users to say “now break that down by device.”
- Explanations: Show the join path, metric definition, and filters used; enable one-click edits (change time window, add a WHERE clause).
Dialect Differences to Watch
- Date functions: date_trunc vs DATE_TRUNC vs DATETRUNC; interval syntax.
- String ops: ILIKE vs LOWER + LIKE; regex availability.
- Quoting: Backticks, double quotes, or brackets for identifiers.
- Limits and sampling: LIMIT vs TOP vs QUALIFY; APPROX functions.
- Null semantics: COALESCE defaults and DISTINCT with nulls.
A dialect adapter can normalize logical operations and render warehouse-specific SQL just-in-time.
Testing and CI for Text-to-SQL
Reliability requires disciplined testing.
- Gold sets: Curate a versioned suite of questions with expected SQL and result hashes.
- Mutation tests: Randomly paraphrase questions and verify stable execution.
- Schema drift alarms: Detect breaking changes (renamed columns, altered types) and auto-update prompts/contexts.
- Cost guards: Unit tests that fail if a query exceeds expected bytes scanned or loses an index.
- Shadow runs: Compare new model/version against production logs before rollout.
Observability and Human-in-the-Loop
- Traces: Capture prompt, context size, token counts, candidate SQLs, and ranking features.
- Dashboards: Track acceptance, latency, and block reasons.
- Review queues: Analysts adjudicate failures; corrections become new few-shot examples or training data.
- Continuous learning: Periodically retrain or refresh synonym tables from accepted queries.
Performance and Cost Tips
- Retrieve narrowly: Only include schema elements likely to be relevant.
- Cache aggressively: Memoize answers for repeated questions with identical filters.
- Precompute heavy metrics: Use materialized views for expensive aggregations.
- Limit first: Apply closed-open ranges and LIMIT defaults; require explicit overrides for large extractions.
- Batch clarifications: Ask one concise follow-up rather than generating multiple costly candidates.
Future Directions
- Cross-database generalization: Better transfer across schemas without fine-tuning.
- Program-of-thought planning: Generate an intermediate plan (joins, filters, metrics) then render SQL.
- Semantic constraints: Use business rules (e.g., “revenue cannot be negative”) to catch logical errors.
- Self-healing agents: Closed-loop repair using execution traces and unit tests.
A Practical Checklist
- Define and document your core metrics.
- Build a schema retrieval service with PK/FK, descriptions, and synonyms.
- Use constrained decoding and function allow-lists.
- Enforce read-only execution with row/column-level security.
- Implement dry-run gating, timeouts, and cost budgets.
- Evaluate with exact match, execution accuracy, and human review.
- Log everything; create a review pipeline; keep prompts and contexts versioned.
With the right scaffolding—schema-aware retrieval, grammar constraints, safety gates, and thoughtful prompts—text-to-SQL can reliably turn plain language into correct, efficient queries that put data at everyone’s fingertips.
Related Posts
Instruction Tuning LLMs: An End-to-End Practical Tutorial
A practical, end-to-end tutorial on instruction tuning LLMs: data design, LoRA/QLoRA training code, evaluation, deployment, and production tips.
Building Social Media Insights with AI Sentiment Analysis APIs: Architecture, Metrics, and Code
How to integrate AI sentiment analysis APIs into social media stacks—architecture, metrics, sample code, and best practices for reliable, real-time insights.
LLM Fine-Tuning Dataset Preparation: An End-to-End Guide
A step-by-step guide to preparing high-quality datasets for LLM fine-tuning, from sourcing and cleaning to formats, safety, splits, and evaluation.