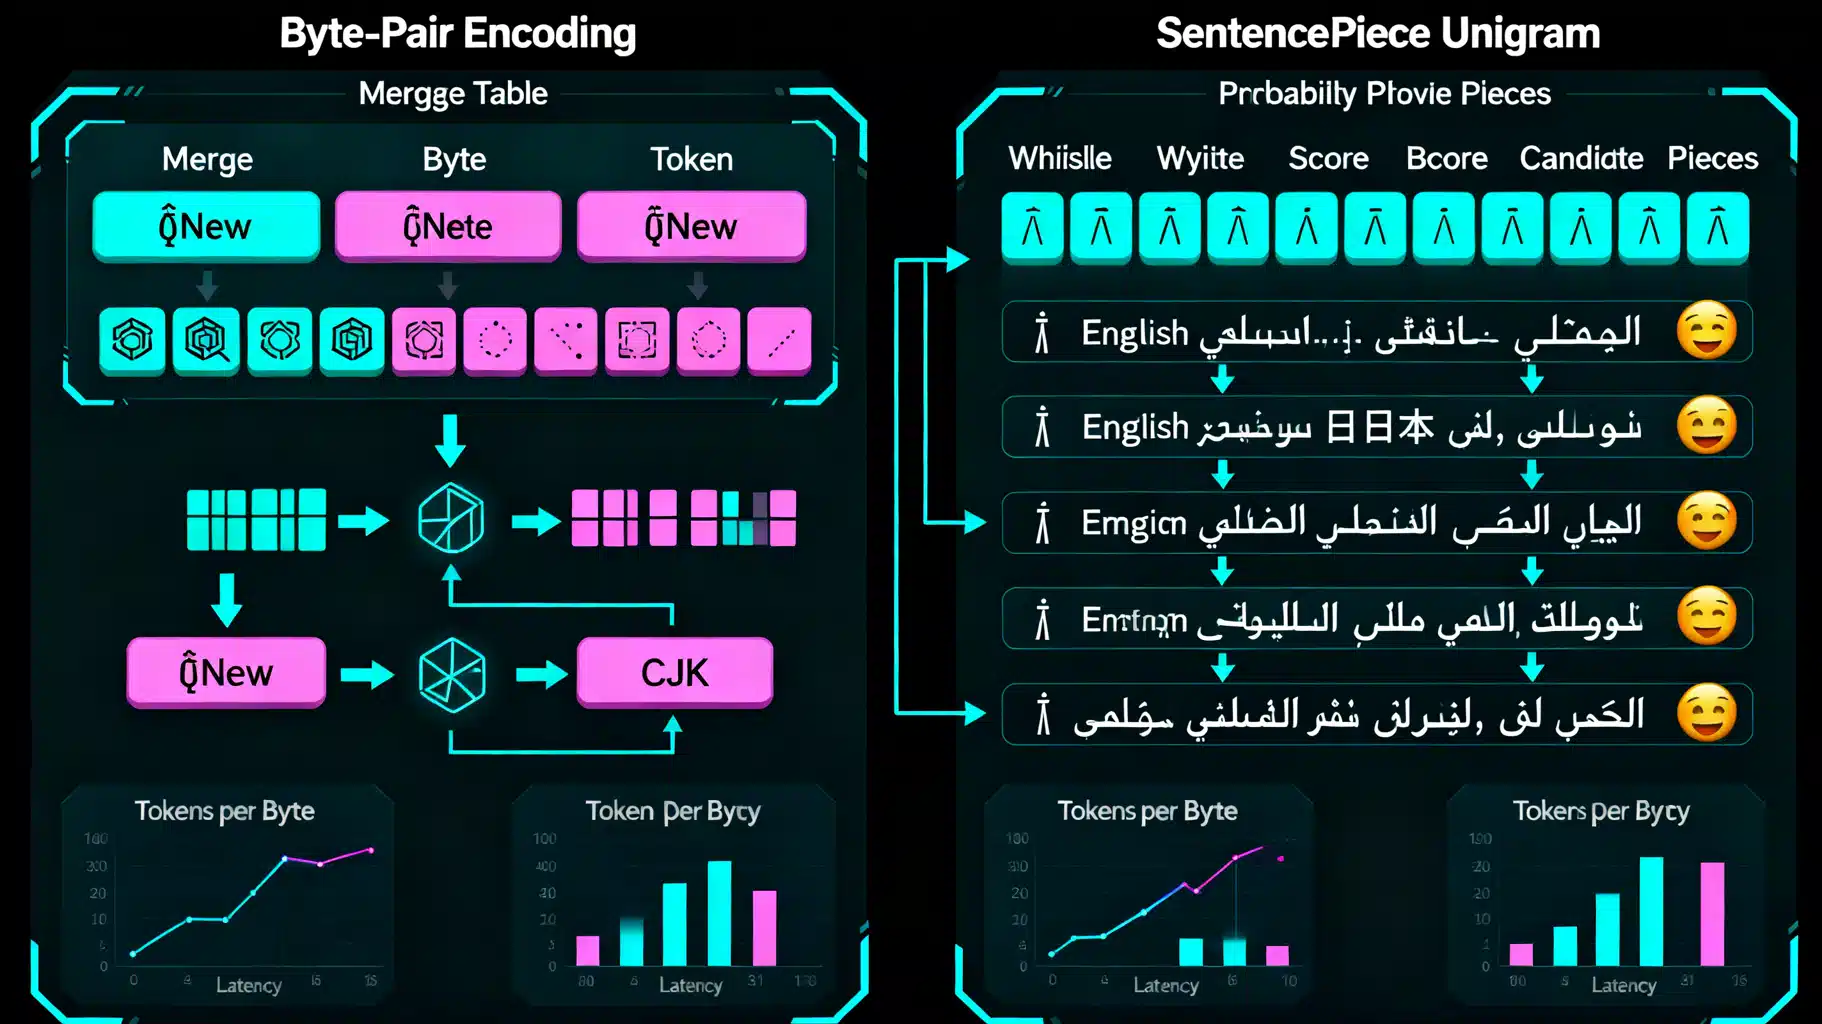
LLM Tokenizer Comparison: BPE vs SentencePiece (Unigram and SP‑BPE)
Clear comparison of BPE and SentencePiece tokenizers for LLMs: algorithms, Unicode handling, training, benchmarks, and guidance to choose the right one.
A vendor-neutral, practical framework to evaluate and compare AI-powered code completion tools for real-world teams.
A practical 2026 guide to comparing AI image upscaling APIs—how to benchmark quality, speed, and cost, and what to demand for production integration.
A buyer’s guide to AI speech-to-text APIs: how to compare accuracy, latency, privacy, cost, and run your own benchmarks—without vendor hype.
A practical guide to API performance benchmarking tools, metrics, and methods with examples using k6, JMeter, Locust, Gatling, wrk, and Vegeta.
A practical guide to LLM benchmarking: metrics, datasets, protocols, stats, and pitfalls, with checklists and code for reliable, reproducible evaluations.