Building an AI Customer Churn Prediction API: Architecture, Endpoints, and Best Practices
A practical guide to designing an AI churn prediction API—architecture, data/modeling choices, endpoints, MLOps, metrics, and code examples.
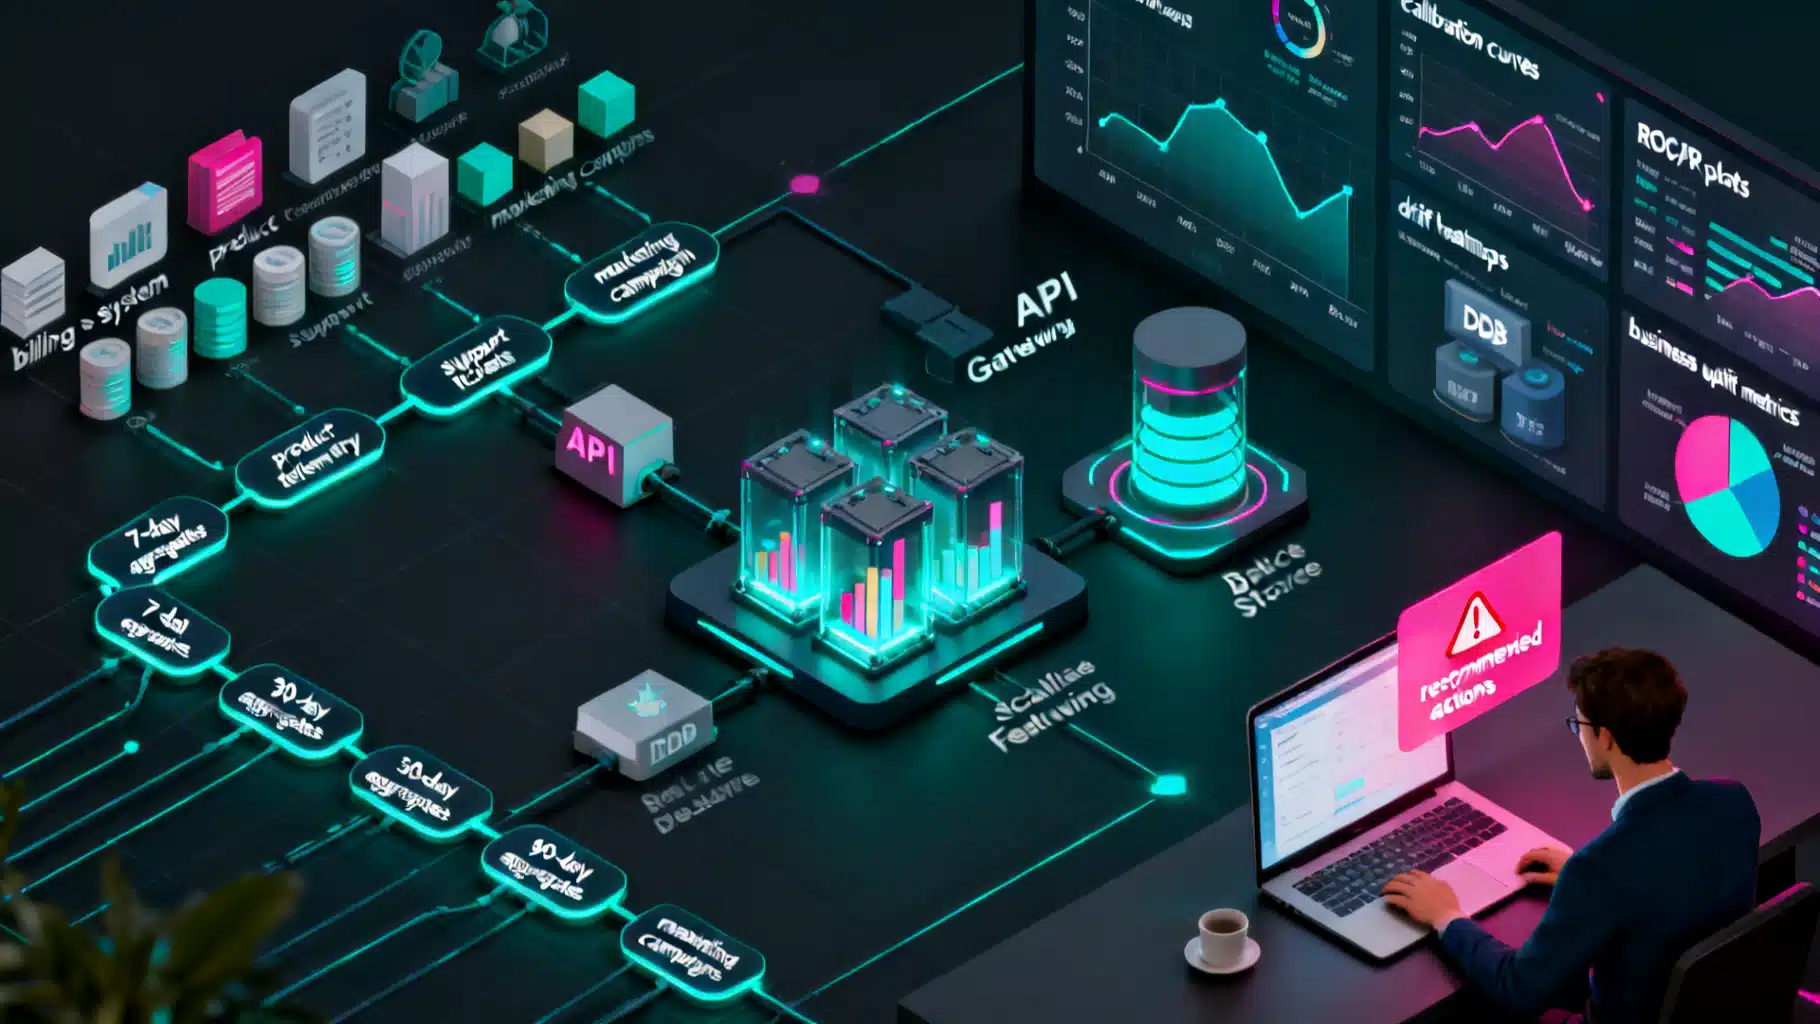
Image used for representation purposes only.
Why a churn prediction API
Customer churn silently erodes revenue and growth. Turning churn risk into a real-time signal—available wherever decisions are made—requires more than a good model. It demands an API that is reliable, secure, explainable, and easy to integrate across channels like CRM, billing, support, and marketing automation. This article walks through how to design, build, and operate an AI churn prediction API end to end.
What the API should deliver
A production-grade churn prediction API should provide:
- Low-latency scoring for a single customer (synchronous) and fast batch scoring for campaigns.
- Clear, calibrated probabilities with optional risk bands.
- Explanations that highlight top drivers for each prediction.
- Feedback ingestion to capture outcomes and power continuous learning.
- Versioning, auditability, and robust monitoring.
Reference architecture
A practical architecture separates data, modeling, and serving so each can scale independently:
-
Data sources
- Transactional: purchases, invoices, contract terms, renewals.
- Behavioral: product usage events, page views, session metrics.
- Support: tickets, CSAT, NPS, call logs.
- Marketing: campaign touches, email opens, offers redeemed.
- Context: pricing plans, geography, device, tenure.
-
Feature engineering
- Offline feature pipelines (e.g., Spark/SQL/DBT) compute aggregates over lookback windows (7/30/90 days).
- Online feature store (e.g., Redis, DynamoDB) serves the freshest features for real-time scoring.
- Consistency contracts ensure offline and online features use identical definitions.
-
Modeling
- Start with strong baselines (regularized logistic regression, gradient-boosted trees) before exploring deep models or survival analysis.
- Handle class imbalance (focal loss, class weights, stratified sampling).
- Calibrate probabilities (Platt/ISOTONIC) and validate stability across cohorts and time.
-
Model serving
- Stateless inference service (REST or gRPC) with autoscaling, request/response logging, and request idempotency keys.
- Optional streaming scoring via event bus (Kafka/Kinesis/PubSub) for high-volume telemetry.
-
Monitoring and governance
- Inference metrics: latency, error rates, throughput, cache hit rate.
- Model metrics: AUC/PR-AUC, calibration, drift (data, prediction, target), stability by segment.
- Business KPIs: uplift vs. control, retention rate, net revenue saved.
Data design and leakage prevention
Building a trustworthy churn model starts with a precise label and timeframe.
- Label definition: churn = no purchase/usage/renewal within a defined horizon (e.g., 30/60/90 days after reference date) or explicit cancelation event.
- Observation window: features computed up to reference date t; prediction horizon t→t+H; do not include any signals beyond t to avoid leakage.
- Cohorts: segment by product tier, tenure, or geography to check metric stability.
- Cold start: implement sensible defaults for new customers with sparse history.
Minimum feature set to start:
- Customer: tenure_days, plan, MRR/ARPU, region.
- Engagement: weekly_active_days_4w, last_seen_days, sessions_7d.
- Value: invoices_3m, refunds_3m, discounts_ratio_3m.
- Support: tickets_30d, avg_first_response_time_30d, csat_90d.
- Marketing: last_offer_days, email_opens_30d, channel_mix.
Modeling approaches
- Interpretable baselines: logistic regression with monotonic constraints on key features.
- Tree ensembles: XGBoost/LightGBM/CatBoost for nonlinearity and categorical handling.
- Time-to-event: Cox or parametric survival models to forecast churn hazard over time.
- Uplift modeling: two-model or DR-learner to predict the incremental effect of save actions.
- Calibration: reliability plots; apply isotonic regression if needed.
API design: endpoints and contracts
Design for clarity, safety, and evolution. A typical REST surface:
- POST /v1/score
- Purpose: real-time probability for one customer.
- Request idempotency: Idempotency-Key header to de-duplicate retries.
- POST /v1/batch/score
- Purpose: asynchronous large-scale scoring. Returns job_id and completion webhook.
- POST /v1/explain
- Purpose: per-customer feature attributions (e.g., SHAP) and top drivers.
- POST /v1/feedback
- Purpose: submit ground-truth outcomes (churned/retained) and treatment metadata for retraining.
- GET /v1/schema
- Purpose: feature dictionary with types, ranges, freshness SLAs.
- GET /v1/health and GET /v1/metrics
- Purpose: liveness/readiness; Prometheus-style operational metrics.
Example request/response
Request (single score):
curl -X POST https://api.acme.ai/churn/v1/score \
  -H "Authorization: Bearer $TOKEN" \
  -H "Content-Type: application/json" \
  -H "Idempotency-Key: 5f8b7d2e-2a0d-4ac2-8b7d-2111a0c9a8f0" \
  -d '{
    "customer_id": "c_82931",
    "timestamp": "2026-09-18T15:03:00Z",
    "features": {
      "tenure_days": 412,
      "plan": "pro_monthly",
      "mrr": 99.0,
      "weekly_active_days_4w": 2.1,
      "last_seen_days": 9,
      "tickets_30d": 3,
      "email_opens_30d": 0
    }
  }'
Response:
{
  "customer_id": "c_82931",
  "model_version": "2026.09.01_gbm_v42",
  "churn_probability": 0.76,
  "risk_band": "high",
  "top_drivers": [
    {"feature": "last_seen_days", "direction": "+", "contribution": 0.21},
    {"feature": "weekly_active_days_4w", "direction": "-", "contribution": 0.18},
    {"feature": "tickets_30d", "direction": "+", "contribution": 0.12}
  ],
  "calibration": {"method": "isotonic", "confidence": 0.92},
  "request_id": "rq_01J7X9YZ3J4W3N9G4ZQJ7HQ4V4"
}
Batch scoring:
curl -X POST https://api.acme.ai/churn/v1/batch/score \
  -H "Authorization: Bearer $TOKEN" \
  -F "file=@features_2026-09-18.parquet" \
  -F "notify_url=https://app.example.com/webhooks/churn_completed"
Webhook payload on completion:
{
  "job_id": "jb_63a1c",
  "created_at": "2026-09-18T06:10:00Z",
  "rows_scored": 128394,
  "artifact_uri": "s3://acme-churn/jobs/jb_63a1c/scores.parquet",
  "summary": {"p50": 0.18, "p90": 0.62, "p99": 0.87, "share_high_risk": 0.14}
}
SDK patterns
Offer thin client libraries that wrap authentication, retries with exponential backoff, and JSON validation.
Python example:
import requests
from typing import Dict

class ChurnClient:
    def __init__(self, base_url: str, token: str, timeout: int = 3):
        self.base_url = base_url.rstrip('/')
        self.s = requests.Session()
        self.s.headers.update({
            'Authorization': f'Bearer {token}',
            'Content-Type': 'application/json'
        })
        self.timeout = timeout

    def score(self, customer_id: str, features: Dict, ts: str):
        payload = {"customer_id": customer_id, "timestamp": ts, "features": features}
        r = self.s.post(f"{self.base_url}/v1/score", json=payload, timeout=self.timeout)
        r.raise_for_status()
        return r.json()
MLOps: training, deployment, and rollback
- Continuous training: retrain monthly or when drift is detected (e.g., PSI > 0.2 or target rate shift).
- Versioning: immutable model IDs with full lineage (code hash, data snapshot, feature schema, training config).
- Promotion workflow: shadow deploy → canary (5–10%) → full rollout, with automatic rollback on SLO breach.
- A/B testing: measure retention uplift and net revenue impact, not just ROC AUC.
- Reproducibility: containerize training and inference; pin dependencies; record random seeds.
Metrics that matter
Optimize for actionability, not just discrimination:
- Discrimination: ROC AUC, PR AUC (especially with imbalance).
- Calibration: Brier score; reliability curves.
- Business: lift at K (e.g., top 10%), expected value per contacted user, incremental retention, CAC payback.
- Operations: p95 latency, error budget, timeouts, queue depth, cost per 1k predictions.
Example target SLOs:
- p95 latency ≤ 80 ms for single-customer scores.
- Availability ≥ 99.9% monthly.
- Calibration error (ECE) ≤ 0.03 on most recent cohort.
Explainability and trust
- Local explanations: SHAP attributions with feature names that are human-readable.
- Segment insights: top drivers by plan or region to guide product improvements.
- Policy constraints: optionally enforce monotonicity (e.g., higher engagement should not increase risk) to avoid counterintuitive outputs.
- Documentation: model cards with training data dates, known limitations, and intended use.
Privacy, security, and compliance
- Data minimization: only collect features that improve signal; avoid unnecessary PII.
- Encryption: TLS in transit; envelope encryption at rest with key rotation.
- Access control: scoped API tokens, least-privilege IAM, audit logs.
- Retention: configurable TTLs for inference logs and features.
- Compliance: document GDPR/CCPA data subject workflows (access, deletion), and honor consent flags.
Integration patterns
- CRM/CDP: push risk scores into Salesforce, HubSpot, or Segment for lifecycle automation.
- Marketing: trigger save offers via email/SMS/push with rate limits and frequency caps.
- Support: surface risk in agent consoles with next-best-action suggestions.
- Billing: pre-renewal outreach for contracts at high risk.
Orchestrating actions and experiments
Predictions alone don’t save customers—actions do.
- Decisioning: map risk bands to treatments (proactive outreach, discounts, education, onboarding call).
- Eligibility: avoid offering discounts to ineligible cohorts; guardrails for revenue impact.
- Experimentation: randomize within eligible high-risk users; measure incremental uplift and margin.
- Learning loop: send outcomes back via /v1/feedback to improve the model and policy.
Scaling, latency, and cost
- Compute: CPU-first for tree models; enable vectorization and batch size 1–16 micro-batching.
- Autoscaling: scale on CPU utilization and queue depth; maintain warm pools to avoid cold starts.
- Caching: cache recent scores for idempotent repeats within a short TTL (e.g., 15 minutes).
- Cost controls: budgets, alerts, per-tenant rate limits; return-early under overload with circuit breakers.
Build vs. buy
- Build when you need custom features, governance, and tight latency budgets across bespoke systems.
- Buy when speed-to-value and integrations matter most; ensure vendor supports your schema, online features, and experiment measurement.
- Hybrid: vendor for infrastructure (feature store/serving), your own models and policies.
Common pitfalls and how to avoid them
- Label leakage: strictly separate observation and outcome windows.
- Misaligned KPIs: optimize for uplift and NPV, not just AUC.
- Overfitting to discounts: measure long-term value, not just immediate saves.
- Seasonality: train with multiple cycles; use time-based cross-validation.
- Drifting funnels: watch for product changes that alter event semantics; update feature contracts.
30-60-90 day rollout plan
- Days 1–30: define label and schema, build offline features, train baseline model, publish /v1/score, instrument monitoring.
- Days 31–60: add explanations, batch endpoint, feedback loop, first canary; integrate with CRM and marketing tools.
- Days 61–90: run controlled experiment, deploy uplift policy, harden SLOs, schedule monthly retraining.
Conclusion
An AI churn prediction API is the connective tissue between data science and revenue operations. When it pairs calibrated models with reliable infrastructure, tight privacy controls, and closed-loop experimentation, it turns risk signals into measurable retention gains. Start with clear labels and strong baselines, ship a minimal but robust API surface, then iterate with drift-aware training and uplift-focused experiments. The result is not just fewer cancellations—but a system that continuously learns how to keep customers successful.
Related Posts
Designing an AI Content Personalization API: Architecture, Endpoints, and Best Practices
Practical blueprint for an AI content personalization API: architecture, endpoints, models, metrics, latency, and safety—built to scale.
Automating AI Data Labeling with APIs: A Practical Blueprint for Scale
Design, build, and scale an API-driven data labeling pipeline with quality gates, active learning, and strong governance.
Deploying Small Language Models at the Edge: Architecture, Optimization, and Operations
A practical guide to selecting, optimizing, and operating small language models for edge deployment—latency, memory, tooling, and MLOps.