Build an AI‑Powered Recommendation System: A Practical, End‑to‑End Tutorial
Build and deploy an AI-powered recommendation system end-to-end: content-based, collaborative filtering, deep retrieval, evaluation, and FastAPI serving.
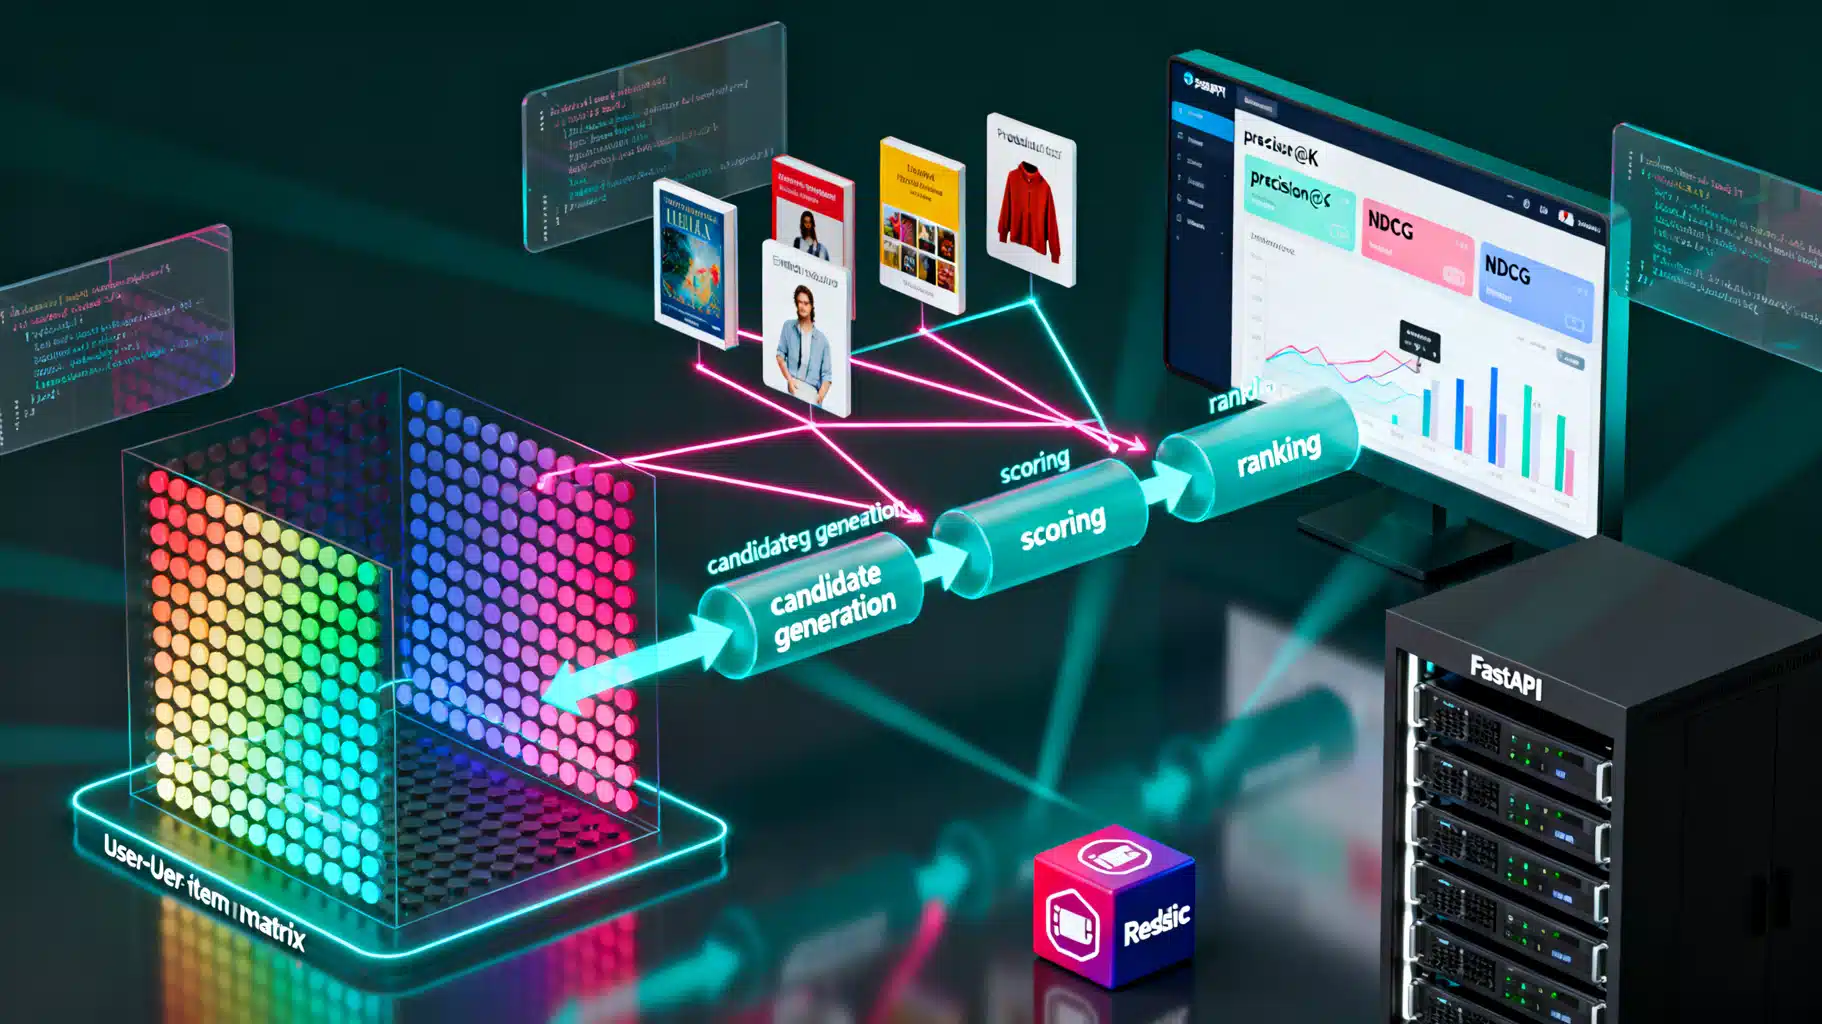
Image used for representation purposes only.
Overview
Recommendation systems quietly power the most engaging products on the web: shopping, news, music, video, and even developer tools. In this tutorial, you’ll build an AI‑powered recommender end‑to‑end: from data modeling and baseline algorithms to hybrid ranking, offline evaluation, and real‑time serving. You’ll leave with runnable code snippets and a mental model you can adapt to your domain.
What We’ll Build
We’ll implement three complementary recommenders and blend them:
- Content‑based filtering: recommend items similar to what a user is viewing.
- Collaborative filtering: learn user and item embeddings from implicit feedback.
- Two‑tower deep retrieval (optional): scalable candidate generation using neural embeddings.
We’ll also cover:
- Data schemas and preprocessing for implicit feedback
- Metrics: precision@K, recall@K, MAP@K, and NDCG@K
- Cold‑start strategies and safety filters
- Serving with FastAPI and caching with Redis
Reference Data Model
Assume you have two CSVs:
- interactions.csv: user_id, item_id, event_type, ts
- items.csv: item_id, title, description, tags, category, price
Map events to implicit strength weights you can tune later:
- view: 1.0
- add_to_cart: 2.0
- purchase: 3.0
Environment Setup
Use Python 3.10+.
pip install pandas numpy scipy scikit-learn implicit lightfm \
    tensorflow tensorflow-recommenders \
    fastapi uvicorn redis
Tip: If you don’t need the neural model, skip TensorFlow packages.
Data Loading and Preparation
import pandas as pd
import numpy as np
from scipy.sparse import coo_matrix

# Load data
inter = pd.read_csv('interactions.csv')
items = pd.read_csv('items.csv')

# Map implicit strengths
strength_map = {'view': 1.0, 'add_to_cart': 2.0, 'purchase': 3.0}
inter['strength'] = inter['event_type'].map(strength_map).fillna(0.5)

# Optional: recency weighting (e.g., exponential decay)
# Newer interactions count more; tune the half_life_days parameter
half_life_days = 30
inter['ts'] = pd.to_datetime(inter['ts'])
max_ts = inter['ts'].max()
age_days = (max_ts - inter['ts']).dt.days.clip(lower=0)
inter['decay'] = np.exp(-np.log(2) * age_days / half_life_days)
inter['confidence'] = inter['strength'] * inter['decay']

# Build id maps for a compact index space
uid2idx = {u:i for i,u in enumerate(inter['user_id'].unique())}
iid2idx = {i:j for j,i in enumerate(items['item_id'].unique())}
idx2uid = {v:k for k,v in uid2idx.items()}
idx2iid = {v:k for k,v in iid2idx.items()}

# Align interactions to indexed space and drop unknown items
inter = inter[inter['item_id'].isin(iid2idx)]
rows = inter['user_id'].map(uid2idx)
cols = inter['item_id'].map(iid2idx)
vals = inter['confidence'].astype('float32')

# Sparse user–item matrix (CSR preferred by most libs)
ui = coo_matrix((vals, (rows, cols)),
                shape=(len(uid2idx), len(iid2idx))).tocsr()
Content‑Based Recommender (TF‑IDF + Cosine)
Great for cold‑start items and explainability. We’ll vectorize item text.
from sklearn.feature_extraction.text import TfidfVectorizer
from sklearn.metrics.pairwise import cosine_similarity

# Build item text field
items['text'] = (
    items['title'].fillna('') + ' ' +
    items['description'].fillna('') + ' ' +
    items['tags'].fillna('').str.replace(',', ' ')
)

vectorizer = TfidfVectorizer(max_features=50000, ngram_range=(1,2), stop_words='english')
X_items = vectorizer.fit_transform(items['text'])  # shape: [n_items, d]

# Precompute similarity blocks on demand to avoid O(n^2) memory if large
from sklearn.preprocessing import normalize
Xn = normalize(X_items)

def similar_items(item_id, k=20, exclude_self=True):
    j = iid2idx.get(item_id)
    if j is None: return []
    sims = cosine_similarity(Xn[j], Xn).ravel()
    if exclude_self:
        sims[j] = -1
    top_idx = sims.argsort()[::-1][:k]
    return [(idx2iid[i], float(sims[i])) for i in top_idx]

# User-to-content: aggregate by items the user interacted with
from collections import defaultdict

def content_recommend_for_user(user_id, k=50):
    u = uid2idx.get(user_id)
    if u is None:  # cold-start user fallback
        # popularity baseline
        pop = np.asarray(ui.sum(axis=0)).ravel()
        top = pop.argsort()[::-1][:k]
        return [(idx2iid[i], float(pop[i])) for i in top]

    user_row = ui.getrow(u)
    seen = set(user_row.indices)
    # Build a pseudo-profile: mean of item TF-IDF vectors for items user engaged with
    if user_row.nnz == 0:
        return content_recommend_for_user(-1, k)  # fallback to popularity

    profile = Xn[sorted(list(seen))].mean(axis=0)
    sims = cosine_similarity(profile, Xn).ravel()
    sims[list(seen)] = -1  # filter seen items
    top_idx = sims.argsort()[::-1][:k]
    return [(idx2iid[i], float(sims[i])) for i in top_idx]
Pros:
- Explainable (you can show matching terms)
- Works for new items
Cons:
- Ignores collaborative signals and serendipity
Collaborative Filtering with Implicit ALS
Matrix factorization on implicit feedback is a strong baseline and scales well.
import implicit
from implicit.als import AlternatingLeastSquares

# implicit expects item-user CSR by default for speed
iu = ui.T.tocsr()

# Hyperparameters to tune via validation
factors = 128
regularization = 1e-2
alpha = 40.0  # confidence scaling for implicit feedback
iterations = 20

# Apply confidence scaling: Cui = 1 + alpha * Rui (Rui are raw counts/strengths)
C = iu.copy().astype('float32')
C.data = 1.0 + alpha * C.data

als = AlternatingLeastSquares(factors=factors,
                              regularization=regularization,
                              iterations=iterations,
                              random_state=42)
als.fit(C)

# Recommend for a user
def cf_recommend_for_user(user_id, k=50, filter_seen=True):
    u = uid2idx.get(user_id)
    if u is None:
        # popularity fallback
        pop = np.asarray(ui.sum(axis=0)).ravel()
        top = pop.argsort()[::-1][:k]
        return [(idx2iid[i], float(pop[i])) for i in top]

    # implicit takes user_items as item-user matrix columns
    user_items = iu.T.tocsr()[u]
    ids, scores = als.recommend(userid=u, user_items=user_items, N=k, filter_already_liked_items=filter_seen)
    return [(idx2iid[i], float(s)) for i,s in zip(ids, scores)]
Pros:
- Captures collaborative patterns and long‑tail interests
- Fast at inference after training
Cons:
- Struggles with truly new users/items without interactions
Hybrid Blending (Content + Collaborative)
Blend normalized scores to get the best of both worlds.
from sklearn.preprocessing import MinMaxScaler

def hybrid_recommend_for_user(user_id, k=50, w_cf=0.7, w_cb=0.3):
    cf = dict(cf_recommend_for_user(user_id, k=200))
    cb = dict(content_recommend_for_user(user_id, k=200))

    # Union of candidates
    all_items = set(cf) | set(cb)

    # Normalize scores separately
    def normalize(scores):
        if not scores: return {}
        arr = np.array(list(scores.values())).reshape(-1,1)
        scaled = MinMaxScaler().fit_transform(arr).ravel()
        return {k: float(v) for k,v in zip(scores.keys(), scaled)}

    cf_n = normalize(cf)
    cb_n = normalize(cb)

    blended = {}
    for it in all_items:
        blended[it] = w_cf * cf_n.get(it, 0.0) + w_cb * cb_n.get(it, 0.0)

    top = sorted(blended.items(), key=lambda x: x[1], reverse=True)[:k]
    return top
Tuning tip: grid‑search w_cf and w_cb against NDCG@K on a validation split.
Optional: Two‑Tower Deep Retrieval with TFRS
Two‑tower models learn separate user and item encoders and use dot‑product for fast retrieval via ANN.
# Minimal sketch; see TFRS docs for full pipeline
import tensorflow as tf
import tensorflow_recommenders as tfrs

class TwoTower(tfrs.models.Model):
    def __init__(self, user_vocab, item_vocab, dim=64):
        super().__init__()
        self.user_model = tf.keras.Sequential([
            tf.keras.layers.StringLookup(vocabulary=user_vocab),
            tf.keras.layers.Embedding(len(user_vocab)+1, dim)
        ])
        self.item_model = tf.keras.Sequential([
            tf.keras.layers.StringLookup(vocabulary=item_vocab),
            tf.keras.layers.Embedding(len(item_vocab)+1, dim)
        ])
        self.task = tfrs.tasks.Retrieval(metrics=tfrs.metrics.FactorizedTopK(
            candidates=tf.data.Dataset.from_tensor_slices(item_vocab).batch(128).map(self.item_model)
        ))
    def compute_loss(self, features, training=False):
        user_emb = self.user_model(features['user_id'])
        item_emb = self.item_model(features['item_id'])
        return self.task(user_emb, item_emb)
Export the item tower to an ANN index (e.g., ScaNN, FAISS) for millisecond candidate generation; then re‑rank with your hybrid.
Train/Validation Split (Temporal)
Recommendations are time‑dependent. Use a temporal split to mimic production.
# Split by timestamp: last N days as validation
cutoff = inter['ts'].quantile(0.9)  # last 10% of interactions as validation
train_mask = inter['ts'] < cutoff
valid_mask = ~train_mask

train_inter = inter[train_mask]
valid_inter = inter[valid_mask]
# Rebuild matrices for train, and keep valid for evaluation
Offline Metrics
Focus on ranking metrics; they correlate better with user satisfaction than RMSE on implicit tasks.
from collections import defaultdict

def precision_recall_at_k(recs_by_user, truth_by_user, k=10):
    precs, recs = [], []
    for u in truth_by_user:
        truth = set(truth_by_user[u])
        if not truth:
            continue
        recs_k = [i for i,_ in recs_by_user.get(u, [])[:k]]
        hit = len(set(recs_k) & truth)
        precs.append(hit / max(len(recs_k), 1))
        recs.append(hit / len(truth))
    return float(np.mean(precs)), float(np.mean(recs))

def dcg(scores):
    return np.sum([(2**s - 1)/np.log2(i+2) for i,s in enumerate(scores)])

def ndcg_at_k(recs_by_user, truth_by_user, k=10):
    ndcgs = []
    for u in truth_by_user:
        truth = set(truth_by_user[u])
        if not truth: continue
        recs_k = [i for i,_ in recs_by_user.get(u, [])[:k]]
        gains = [1 if i in truth else 0 for i in recs_k]
        ideal = sorted(gains, reverse=True)
        idcg = dcg(ideal)
        ndcgs.append(dcg(gains)/idcg if idcg > 0 else 0)
    return float(np.mean(ndcgs))

# Build truth from validation interactions (one or more per user)
truth_by_user = defaultdict(list)
for _,r in valid_inter.iterrows():
    truth_by_user[r['user_id']].append(r['item_id'])

# Generate recommendations for users in validation set
users_valid = list(set(valid_inter['user_id']))
recs_by_user = {}
for u in users_valid:
    recs_by_user[u] = hybrid_recommend_for_user(u, k=50)

p10, r10 = precision_recall_at_k(recs_by_user, truth_by_user, k=10)
ndcg10 = ndcg_at_k(recs_by_user, truth_by_user, k=10)
print({'precision@10': p10, 'recall@10': r10, 'ndcg@10': ndcg10})
Benchmark against baselines:
- Popularity only
- Content‑only
- Collaborative‑only
- Hybrid (tuned)
Cold‑Start Strategy
- New items: rely on content‑based similarity to existing catalog; boost initial exposure using business priors.
- New users: use trending/popularity by segment (geo, campaign, referrer) and ask for quick preferences (onboarding picks).
- Sparse domains: leverage two‑tower retrieval on metadata features (category, price band, brand).
Safety, Policy, and Business Rules
Layer in rules post‑ranking:
- Blocklist items/categories (compliance).
- Diversity: encourage varied categories to avoid over‑personalization.
- Freshness: decay old items; boost new arrivals.
- Price or margin constraints where applicable.
Real‑Time Serving with FastAPI + Redis Cache
The flow:
- Receive user_id.
- Fetch recent interactions/features (Redis or feature store).
- Generate candidates (ALS or ANN index).
- Blend with content similarity.
- Apply business rules and return.
# app.py
from fastapi import FastAPI
import redis

app = FastAPI()
r = redis.Redis(host='localhost', port=6379, db=0)

# Assume als, Xn, mappings already loaded in memory on startup

def get_recent_items(user_id, limit=50):
    key = f'user:{user_id}:recent'
    vals = r.lrange(key, 0, limit-1)
    return [v.decode('utf-8') for v in vals]

@app.get('/recommendations')
def recommendations(user_id: str, k: int = 20):
    # Try cache first
    cache_key = f'recs:{user_id}:{k}'
    cached = r.get(cache_key)
    if cached:
        return {'user_id': user_id, 'items': eval(cached)}

    recs = hybrid_recommend_for_user(user_id, k=k)

    # Persist short‑lived cache
    r.setex(cache_key, 300, str(recs))  # 5 minutes TTL
    return {'user_id': user_id, 'items': recs}

# Run: uvicorn app:app --reload --port 8000
Deployment tips:
- Containerize and pin library versions.
- Warm caches on rollout to avoid cold latency.
- Use health checks and circuit breakers; fall back to popularity on model errors.
Batch Scoring and Feature Freshness
- Nightly batch job (e.g., Airflow) to retrain ALS and refresh item embeddings.
- Incremental updates: stream new interactions to Redis/Kafka, periodically update user representations.
- Store model artifacts with a registry (versioned ONNX/NPZ files, or TF SavedModel).
Online Experimentation
- A/B test ranking strategies with a guardrail set (latency, error rate) and success metrics (CTR, conversion, dwell time).
- Use a sticky assignment service to avoid user crossover.
- Log exposures (what you showed) to correct for position and exposure bias in analysis.
Common Pitfalls and Fixes
- Training–serving skew: tokenize and normalize text identically online and offline.
- Popularity bias: cap per‑item exposure and introduce diversification.
- Feedback loops: include exploration (e.g., epsilon‑greedy or Thompson sampling in candidate selection).
- Metric mismatch: optimize for ranking metrics during training, not just reconstruction error.
- Scale pain: precompute top‑N for heavy users, and shard ANN indices by category.
Interpreting and Explaining Recommendations
- Content‑based: show matching keywords or sections of description.
- Collaborative: display ‘Because you and similar users liked…’ with a few exemplar items.
- Hybrid: indicate both types (‘Similar to X’ and ‘Popular with people like you’).
Privacy and Compliance
- Minimize PII in training; use stable hashed IDs.
- Honor deletion/opt‑out requests with data lineage and TTLs.
- Consider differential privacy or federated learning if regulations require.
Next Steps
- Replace TF‑IDF with transformer embeddings (e.g., sentence transformers) for richer content signals.
- Move from ALS to Bayesian Personalized Ranking (BPR) or WARP loss (LightFM) for pairwise optimization.
- Add a learning‑to‑rank layer that ingests features from the hybrid and optimizes NDCG directly.
- Productionize ANN with FAISS/HNSW and elastic multi‑stage retrieval.
Checklist
- Data: temporal split, strength + decay, valid ID maps
- Models: content, collaborative, optional two‑tower
- Evaluation: precision@K, recall@K, NDCG@K; compare to baselines
- Serving: FastAPI endpoint, Redis cache, business rules
- Ops: scheduled retraining, model registry, monitoring, and A/B tests
With these building blocks, you can stand up a robust AI‑powered recommendation system that is accurate, fast, and adaptable to real‑world constraints.
Related Posts
Build an AI Recipe Generation API: End-to-End Tutorial with JSON Schema, Validation, and Caching
Build a production-ready AI recipe generation API with JSON schema, prompting, validation, caching, and code in Node.js and Python.
Build an AI Meeting Transcription API: An End-to-End Tutorial
Build a production-ready AI meeting transcription API with streaming, diarization, summaries, and exports. Code samples and architecture included.
Designing an AI Content Personalization API: Architecture, Endpoints, and Best Practices
Practical blueprint for an AI content personalization API: architecture, endpoints, models, metrics, latency, and safety—built to scale.