Field‑Level Permissions in GraphQL: Patterns, Code, and Production Tactics
A practical guide to implementing secure, fast, and auditable field-level permissions in GraphQL—patterns, code examples, and production pitfalls.
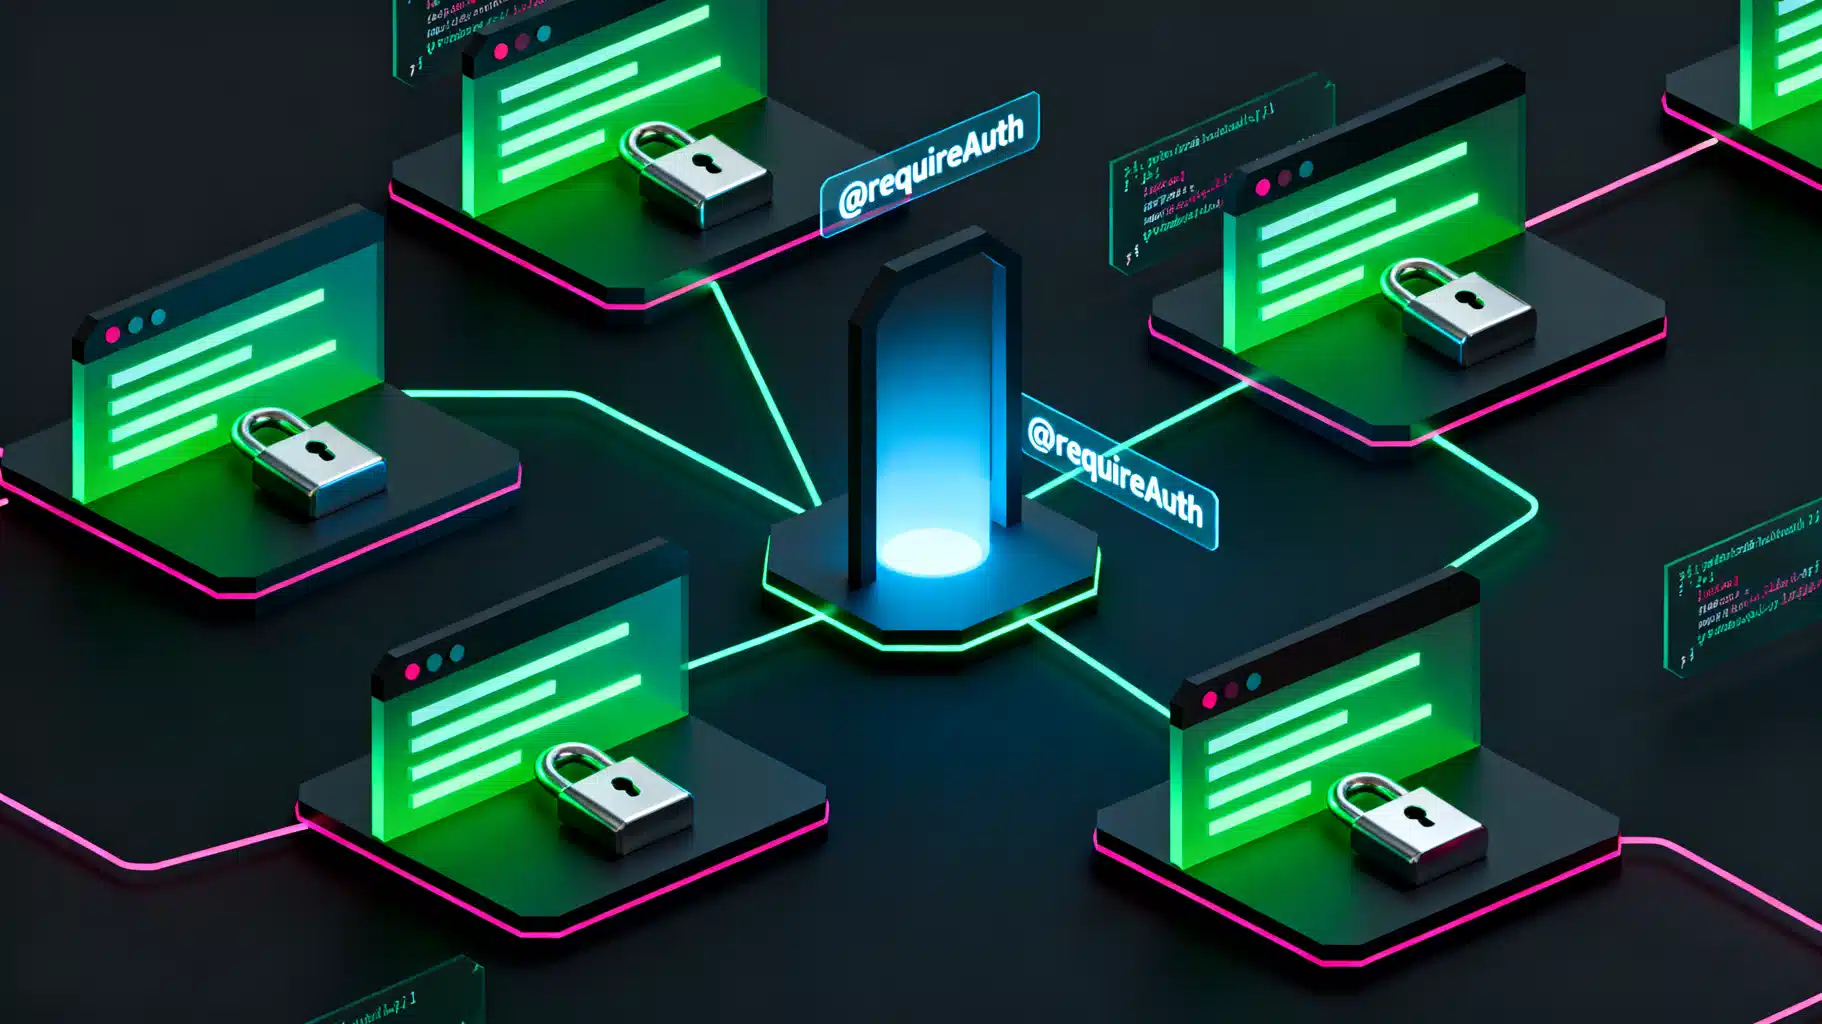
Image used for representation purposes only.
Why Field‑Level Permissions Matter in GraphQL
GraphQL’s power—letting clients ask for exactly what they need—cuts both ways. Without careful authorization, a client can also ask for what they should not see. Type- or route-level checks aren’t enough when sensitive attributes (salary, email, flags, billing info) live alongside public data on the same type. Field-level permissions let you decide, per field and per user, what’s visible, writable, and when.
This article explains conceptual models, common enforcement patterns, production-grade examples, and the sharp edges you’ll want to avoid.
Core Concepts and Vocabulary
- Identity and claims: Who is calling (user, service) and what they bring (roles, org IDs, scopes, ABAC attributes, feature flags)? Typically provided via a JWT or session and attached to the GraphQL context.
- Policy model:
- RBAC: Role-based (admin, editor, viewer).
- ABAC: Attribute-based (resource.ownerId == user.id, tenant matches, row-level predicates).
- ReBAC: Relationship-based (viewer is collaborator on repo).
- Enforcement point: Where checks run—resolver, middleware, schema directive, gateway.
- Result semantics: GraphQL returns partial data with an errors array. Non-null fields bubble nullability violations up the path—design your schema with this behavior in mind when denying access.
When to Use Field‑Level vs. Type‑Level Controls
- Use type-level when an entire type is consistently restricted (e.g., InternalAuditRecord).
- Use field-level when sensitive attributes live on generally accessible types (e.g., User.email visible only to self and admins).
- Combine both: deny-by-default for sensitive types and additional per-field checks for “spicy” fields.
Common Enforcement Patterns
- Inline checks in resolvers
- Pros: Simple, explicit, no tooling required.
- Cons: Duplication, drift, harder to audit.
- Field middleware/wrappers
- Pros: Centralized, testable; can batch policy calls.
- Cons: Requires build-time schema wrapping or a framework that supports middleware.
- Schema directives (@requireAuth, @private, @scope)
- Pros: Policy is visible in SDL, enabling audits and architectural consistency.
- Cons: Implementation complexity; overuse can clutter the SDL.
- Policy engines (OPA, Cedar, Oso) or service calls
- Pros: Consistent, language-agnostic policies; versioned, auditable.
- Cons: Latency, availability, and caching considerations; requires batching.
- Database/ORM row-level security (RLS) + GraphQL
- Pros: Enforces close to data; less app code.
- Cons: Field permissions still needed for non‑persisted/derived fields; DB portability.
Example 1: Inline Checks in a Resolver (TypeScript + Apollo Server)
// schema.graphql
// Field may be null for unauthorized users to avoid non-null bubbling
// Consider making sensitive fields nullable by design

type User {
  id: ID!
  name: String!
  email: String            # restricted to self or admin
  salary: Int              # restricted to finance role
}

type Query {
  me: User
  user(id: ID!): User
}
// context has user with { id, roles: string[], orgId }
import { GraphQLError } from 'graphql';

const canSeeEmail = (viewer, user) =>
  viewer?.roles?.includes('admin') || viewer?.id === user.id;

const canSeeSalary = (viewer) =>
  viewer?.roles?.includes('finance');

export const resolvers = {
  Query: {
    me: (_r, _a, { user, dataSources }) => user ? dataSources.users.byId(user.id) : null,
    user: (_r, { id }, { dataSources }) => dataSources.users.byId(id),
  },
  User: {
    email: (user, _a, { user: viewer }) => (canSeeEmail(viewer, user) ? user.email : null),
    salary: (user, _a, { user: viewer }) => (canSeeSalary(viewer) ? user.salary : null),
  },
};
Notes:
- Returning null is often better UX than throwing; expose a specific error only when useful. Make sensitive fields nullable to prevent query failure for other fields.
- For mutations, fail fast with an authorization error.
Example 2: Field Middleware Wrapper
import { mapSchema, getDirective, MapperKind } from '@graphql-tools/utils';
import { defaultFieldResolver, GraphQLSchema } from 'graphql';

// SDL: directive to express intent
// directive @requireAuth(role: Role, owns: Boolean = false) on FIELD_DEFINITION

export function authDirectiveTransformer(schema: GraphQLSchema) {
  return mapSchema(schema, {
    [MapperKind.OBJECT_FIELD]: (fieldConfig) => {
      const directives = getDirective(schema, fieldConfig, 'requireAuth') || [];
      if (directives.length === 0) return fieldConfig;

      const { role, owns } = directives[0];
      const originalResolve = fieldConfig.resolve || defaultFieldResolver;

      fieldConfig.resolve = async (src, args, ctx, info) => {
        const { user } = ctx;
        if (!user) return null; // or throw based on your policy

        if (role && !user.roles?.includes(role)) return null;
        if (owns) {
          // generic ownership check
          const resourceOwnerId = src.ownerId ?? src.id;
          if (!resourceOwnerId || resourceOwnerId !== user.id) return null;
        }

        return originalResolve(src, args, ctx, info);
      };

      return fieldConfig;
    },
  });
}
Benefits:
- Centralizes logic; keeps resolvers clean.
- You can later replace the inline checks with calls to a policy engine.
Example 3: Calling a Policy Engine with Batching
// pseudo-implementation showing batched authorization per request
import DataLoader from 'dataloader';

function makeAuthzLoader(policyClient, user) {
  return new DataLoader(async (items) => {
    // items: [{ action, resource: { type, id, attrs } }]
    const decisions = await policyClient.batchEvaluate({ subject: user, items });
    return decisions; // [true|false]
  }, { cache: false });
}

export const context = async ({ req }) => {
  const user = decodeUser(req.headers.authorization);
  const authz = makeAuthzLoader(policyClient, user);
  return { user, authz };
};

// in resolver
salary: async (user, _a, { authz }) => {
  const allowed = await authz.load({ action: 'read', resource: { type: 'User.salary', id: user.id } });
  return allowed ? user.salary : null;
}
Tips:
- Represent each sensitive field as a resource (User.salary) with attributes for ABAC predicates.
- Batch requests to avoid per-field round trips.
Mutations and Input Field Permissions
Authorization isn’t just for reads:
- Validate inputs per field. Example: only admins can set User.role; only self can change password.
- Use input object directives (or server-side schemas) to validate write access.
- Prefer “fail with an auth error” over silently ignoring unauthorized input to avoid confusing clients.
// Example guard inside a mutation resolver
updateUser: async (_r, { id, patch }, { user, dataSources }) => {
  if (patch.role && !user.roles.includes('admin')) {
    throw new GraphQLError('Forbidden: cannot change role', { extensions: { code: 'FORBIDDEN' } });
  }
  if (id !== user.id && !user.roles.includes('admin')) {
    throw new GraphQLError('Forbidden: cannot edit other users');
  }
  return dataSources.users.update(id, patch);
}
Subscriptions: Check Twice
- Authorize on subscribe: ensure the client can listen to the topic.
- Authorize on publish: ensure each payload’s fields are filtered (or dropped) based on the current viewer claims; subscriptions can outlive logins, so revalidate or cancel when tokens expire.
Federation and Stitching
- Don’t rely solely on a gateway: if subgraphs are separate trust domains, enforce authorization in each subgraph. Gateways should not grant more than subgraphs allow.
- Annotate permissions consistently across services (shared directives or a policy vocabulary).
- Forward identity context (user ID, roles, tenant) through the gateway—signed, immutable, and minimal.
Designing for Safe Nullability and Error Handling
- Make sensitive fields nullable to allow partial results for unauthorized viewers.
- Use error paths and extension codes (e.g., FORBIDDEN) sparingly; avoid leaking existence of hidden records.
- For “presence leaks” (does a record exist?), consider returning null for the parent object if the user cannot see any of its fields.
Performance and Caching
- Batch authorization: DataLoader or custom aggregators to reduce N×M checks.
- Cache policy decisions per request; optionally short‑term per user with a safe invalidation strategy.
- Response caching: vary by identity (Vary: Authorization) or use user‑scoped cache keys; never cache private responses publicly.
- Complexity and depth limits: reduce attack surface for probing sensitive fields at scale.
- Persisted queries and safelists: prevent ad‑hoc probing in production.
Auditing and Observability
- Emit structured authorization logs: subject, resource, action, decision, reason, correlation ID.
- Metrics: decision counts, deny rates, latency percentiles for policy checks.
- Tracing: annotate spans with field paths to identify hot spots.
Testing Strategy
- Unit tests per policy rule (role, ownership, tenant).
- Contract tests for directives and middleware: verify SDL annotations do what they claim.
- Golden tests for “partial result” semantics: same query under different identities.
- Negative tests: ensure hidden fields remain undiscoverable via errors or timing.
Schema Authoring Guidelines
- Mark risky fields early. Adopt an internal convention: all PII/financial fields must carry an auth directive.
- Prefer enums/scopes over free‑text roles to reduce typos.
- Co-locate ownership hints (ownerId) on types to simplify reusable checks.
- Document policies in SDL comments; generate docs to keep product and security aligned.
Threats and Pitfalls to Avoid
- Allow-by-default: new fields ship without checks. Use lint rules or CI to fail builds when sensitive fields lack directives/tests.
- Leaky introspection: directives that disclose rules can help attackers map your domain. Balance clarity with not revealing internal role names or conditions.
- Overthrowing errors: detailed messages can leak existence or counts. Prefer null + generic errors for sensitive contexts.
- Trusting client-provided identifiers: always re-fetch resources server-side before evaluating ownership.
- One-and-done checks: mutations must re-check per input field and per state transition.
Rollout Checklist
- Define a common “subject” schema (id, roles, tenant, attributes) and attach it to GraphQL context.
- Pick an enforcement pattern (resolver, middleware, directives) and standardize.
- Decide on deny behavior per field: null vs error.
- Add depth/complexity limits and safelists.
- Instrument decisions and set SLOs for policy latency.
- Bake tests and static checks into CI; block merges for missing protections.
Conclusion
Field-level permissions in GraphQL are not just a security hardening detail—they’re essential to delivering least-privilege access while preserving GraphQL’s flexibility. By expressing policy close to the schema, centralizing enforcement, and designing for partial results, you can protect sensitive data without sacrificing developer velocity or client ergonomics.
Related Posts
Designing a REST–GraphQL Hybrid Architecture: Patterns, Trade‑offs, and Playbook
Design a pragmatic REST–GraphQL hybrid: patterns, trade‑offs, caching, security, federation, and migration steps to ship faster without breaking what works.
GraphQL Introspection: Risks, Abuse Patterns, and Production-Ready Mitigations
Understand GraphQL introspection risks and how to secure production APIs: restrict or disable introspection, enforce allowlists, rate limits, and robust auth.
Implementing Custom GraphQL Directives: Patterns, Code, and Pitfalls
A practical guide to designing and implementing custom GraphQL directives with examples in TypeScript and Java.