AI Content Safety Moderation Techniques: A Practical Defense-in-Depth Guide
Practical, defense-in-depth techniques for AI content safety across text, image, and audio: policies, classifiers, guardrails, pipelines, and evaluation.
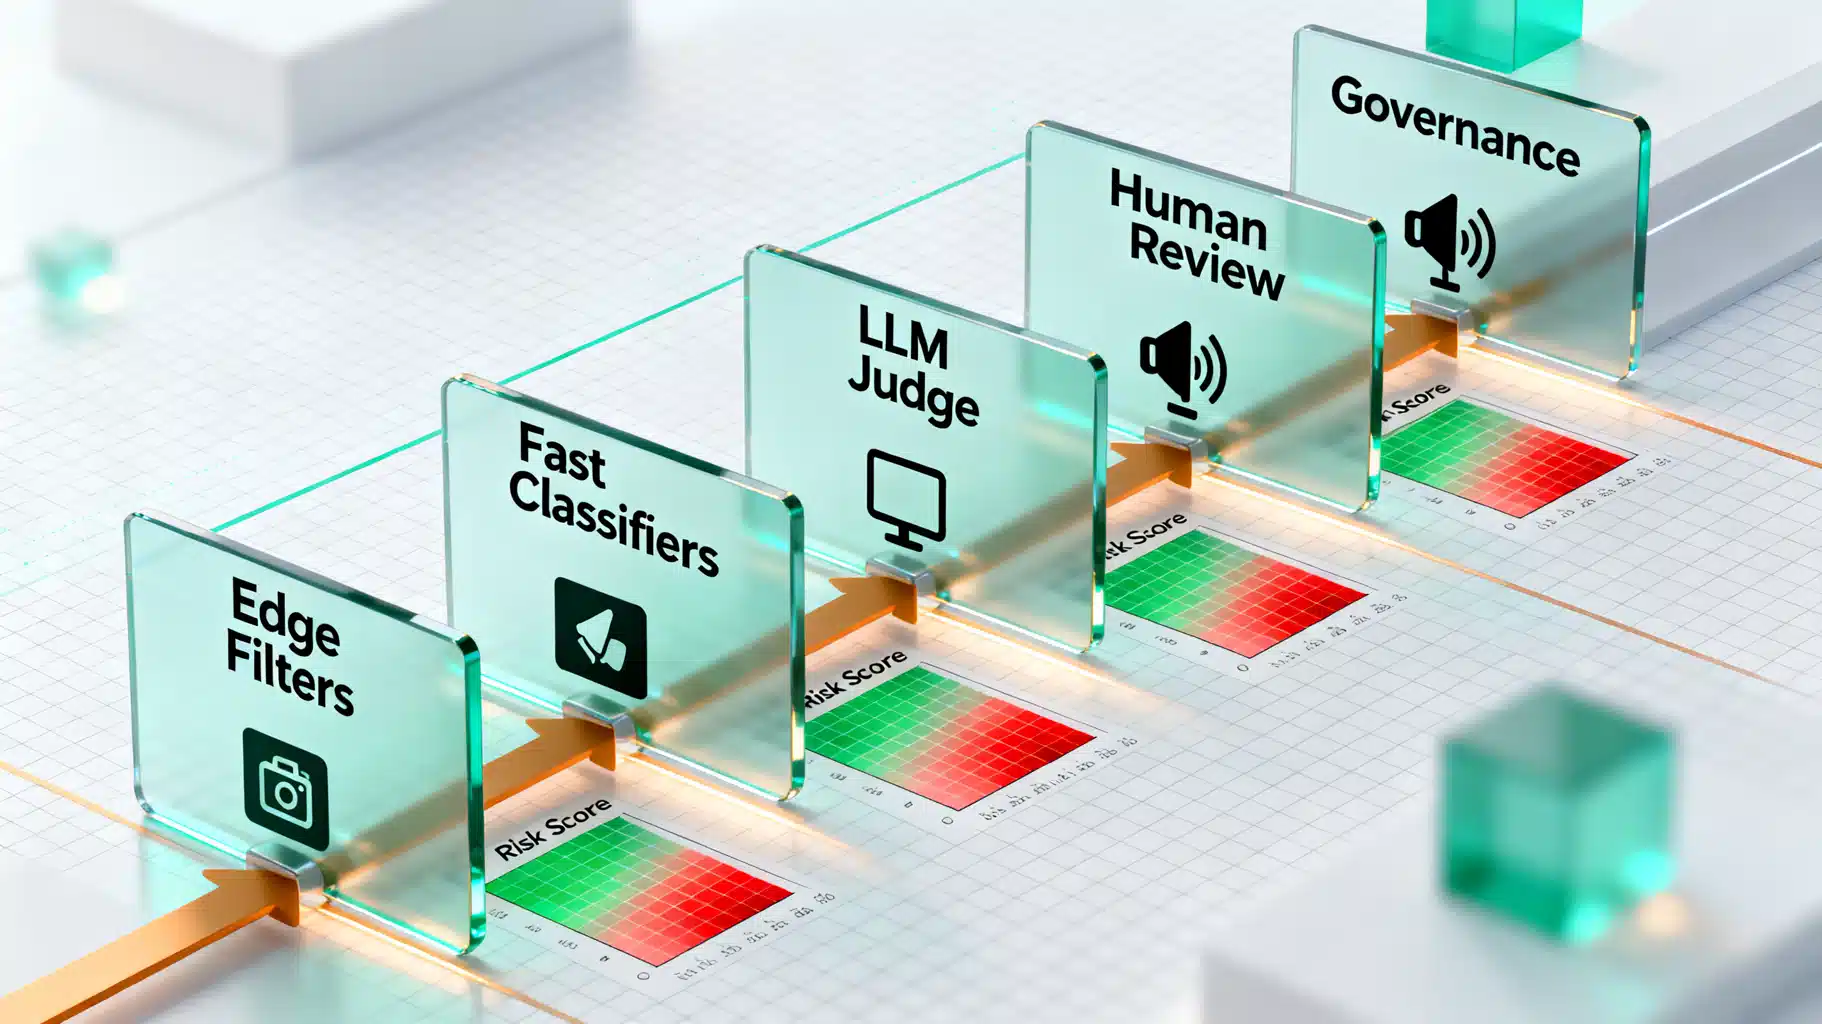
Image used for representation purposes only.
Overview
AI content safety moderation is the discipline of preventing harmful, illegal, or policy‑violating material from being produced, shared, or amplified by AI systems. Effective programs blend policy, machine learning, and operations into a defense‑in‑depth stack that works across modalities (text, image, audio/video), languages, and adversarial tactics. This guide distills practical techniques you can apply today.
What “unsafe” means: a working taxonomy
A clear policy is the root of any safety system. Typical categories include:
- Violence and extremism
- Hate and harassment (protected classes, slurs, demeaning epithets)
- Sexual content (including minors, explicit acts, fetish content)
- Self‑harm and suicide
- Illicit behavior (weapons, drugs, crime enablement)
- Medical, legal, and financial risk advice
- Misinformation and fraud (impersonation, scams)
- Privacy violations (PII exposure, doxxing)
- Intellectual property violations
Each category should define: precise boundaries, examples/counter‑examples, allowed vs disallowed assistance, and escalation rules.
Defense‑in‑depth architecture
Think of moderation as layered gates that trade speed for accuracy:
- Edge filters (microseconds): keyword/regex hash lists, URL/domain blocklists, file‑type sanity checks.
- Fast ML classifiers (milliseconds): lightweight toxicity/hate/sexual content models, PII detectors.
- Contextual analysis (tens to hundreds of ms): LLM‑as‑judge, NLI/entailment, embeddings similarity, conversation memory scanning.
- Human review (seconds to minutes): policy‑trained raters, expert queues (e.g., self‑harm, medical).
- Governance and audit: logs, explanations, incident response, change management.
Use separate pipelines for:
- Pre‑input (prompt/user content) filtering
- In‑generation (token‑level or stepwise) steering
- Post‑output filtering, rewriting, or safe‑completion
- Retrieval/tool safety (restricting tools, filtering retrieved docs)
Core detection techniques
1) Rule‑based filtering
- Deterministic checks: regex, Aho‑Corasick keyword sets, Unicode normalization, homoglyph detection, leetspeak maps.
- Structured PII: Luhn‑validated payment cards, IBAN, SSN patterns, email/phone masks, GPS coordinates.
- Advantages: low latency, explainable; Disadvantages: brittle, high false positives without context.
2) Supervised classifiers
- Text: transformer models (e.g., compact BERT/RoBERTa variants) fine‑tuned on multi‑label safety corpora.
- Image: NSFW/nudity classifiers, weapon/drug detectors, OCR + text moderation for memes.
- Audio: ASR to text for semantic checks; voice biometrics/age estimation only with strong privacy constraints.
- Best practices: class imbalance handling, focal loss, multilingual tuning, calibration (Platt/temperature scaling).
3) Zero/low‑shot reasoning
- NLI/entailment frameworks to ask “Does text entail a policy violation?”
- LLM‑as‑judge with structured rubrics and chain‑of‑thought hidden from users; constrain with system prompts and tool‑use policies.
4) Embeddings and similarity
- Vector search to spot semantically similar known‑bad content or policies examples.
- Useful for obfuscation/jailbreak variants and for clustering novel attack patterns.
5) Safety‑aware generation
- System instructions that encode policy, refusal patterns, and safe‑completion styles.
- Decoding controls: temperature, top‑p, banned tokens, safety‑guided decoding.
- Response shaping: refusal with context, redirect to allowed alternatives, or provide supportive resources (e.g., self‑harm flows).
6) Cross‑modal signals
- Images: combine visual NSFW + face/age heuristics (minimize face recognition without consent); run OCR then text moderation.
- Audio/video: ASR + toxicity/hate; consider prosody only if compliant and necessary (privacy‑sensitive).
Orchestration patterns
- Triage bands: Low, Medium, High risk. Low auto‑allow; Medium route to LLM‑judge; High auto‑block + review.
- Dynamic routing: choose small/fast vs large/accurate models based on risk and SLA.
- Memory scanning: re‑check conversation history and retrieved documents; don’t let earlier unsafe content leak into outputs.
- Tool gating: allowlisted tools/functions; per‑tool eligibility rules; redact model inputs/outputs to tools.
- Rate‑limit and quota: mitigate automated probing and brute‑force jailbreaks.
Generative safety for LLMs
- Prompt hardening: layered system messages, role separation, invisible safety hints, content policies as machine‑readable checklists.
- Injection resistance: strip/neutralize “ignore previous instructions,” markdown code fences that hide payloads, suspicious URL patterns, prompt delimiters.
- Retrieval filtering: before RAG, filter documents by safety; after retrieval, summarize with safety rubric; suppress unsafe sources.
- Tool‑use constraints: schema validation, type checks, side‑effect sandboxing, dry‑run + approval for sensitive actions.
- Safe‑completion modes: when content is disallowed (e.g., self‑harm), provide empathetic language, crisis resources, and encourage seeking help instead of refusal alone.
Adversarial tactics and countermeasures
- Obfuscation: leetspeak, homoglyphs, split tokens → Unicode normalization, fuzzy matching, embeddings.
- Contextual laundering: framing harmful intent as academic or fictional → LLM‑judge with intent inference and use‑case checks.
- Multi‑turn drift: user increments requests across turns → rolling context risk score; re‑evaluate per turn.
- Model evasion: adversarial paraphrases → robust training with counterfactual data augmentation and red‑team corpora.
- Tool abuse: using calculators/browsers to bypass guardrails → strict tool policies, post‑tool moderation of outputs.
Measurement, evaluation, and calibration
Key metrics:
- Precision/recall/F1 per class and macro‑averaged
- ROC/PR curves; cost‑sensitive thresholds tuned to business risk
- False positive rate (creator friction) vs false negative rate (safety risk)
- Block/allow/redirect rates; reviewer queue volume and SLA
- Cross‑language performance, dialectal robustness, code‑switching stability
- Safety regression tests on every release; canary prompts and golden sets
Calibration and thresholds:
- Use temperature or Platt scaling to calibrate classifier probabilities.
- Set per‑category thresholds (e.g., lower tolerance for sexual content involving minors vs general toxicity).
- Employ abstention/“unknown” classes to reduce over‑confident errors.
Data, labeling, and fairness
- Labeling rubric with explicit allowed/disallowed and corner cases; dual independent labels + adjudication.
- Counterfactual data augmentation (e.g., swap demographic terms) for fairness stress tests.
- Active learning: prioritize uncertain or novel samples for labeling.
- Privacy: minimize exposure of sensitive content to raters; blur/redact where possible; secure access controls.
Privacy, security, and compliance considerations
- PII detection and transformation: mask, hash, or generalize (e.g., “a phone number” instead of exact digits).
- Logging: redact sensitive fields by default; segregate access; immutable audit trails.
- Data retention: enforce retention windows; regional storage constraints.
- Legal regimes vary; build adaptable policy layers and jurisdictional toggles.
Operations: humans in the loop
- Triage queues by risk and expertise (e.g., self‑harm specialists).
- Reviewer tooling: side‑by‑side evidence, rationale capture, and policy links.
- QA: blind audits and scorecards; feedback to model training.
- Incident response: on‑call rotations, runbooks, severity matrix, and escalation paths.
Implementation blueprint (90 days)
- Days 0–30: Define policy and taxonomy; deploy edge filters and baseline toxicity/NSFW/PII models; set up logging and dashboards; assemble red‑team prompts.
- Days 31–60: Add LLM‑as‑judge with structured rubrics; implement triage routing; introduce safe‑completion flows; start human review and QA loops.
- Days 61–90: Calibrate thresholds; expand multilingual support; integrate retrieval/tool gating; run adversarial red teams; stand up incident response and governance reviews.
Example: a modular moderation pipeline (Python‑style pseudocode)
class ModerationResult(TypedDict):
    risk: str            # 'low' | 'medium' | 'high'
    categories: dict     # {category: probability}
    actions: list        # ['allow', 'block', 'rewrite', 'review']
    rationale: str


def edge_filters(content:str) -> ModerationResult:
    hits = regex_bank.scan(content_normalize(content))
    pii = pii_detector.find(content)
    if contains_child_sexual_content(hits):
        return {"risk":"high","categories":{"sexual_minors":1.0},
                "actions":["block","review"],"rationale":"deterministic match"}
    risk = "medium" if hits or pii else "low"
    return {"risk":risk, "categories":scores_from_rules(hits, pii),
            "actions":["allow"], "rationale":"edge filters"}


def fast_classifiers(content:str) -> dict:
    return {
        'toxicity': toxicity_model.prob(content),
        'hate': hate_model.prob(content),
        'sexual': nsfw_text_model.prob(content),
        'self_harm': selfharm_model.prob(content),
    }


def llm_judge(content:str, context:str) -> dict:
    prompt = make_safety_prompt(policy=POLICY, content=content, context=context)
    return llm.evaluate(prompt)  # returns per‑category probabilities + rationale


def route(content:str, context:str) -> ModerationResult:
    res = edge_filters(content)
    if res['risk'] == 'high':
        return res
    cls = fast_classifiers(content)
    risk = triage(cls)  # thresholds per category
    if risk == 'low':
        return {"risk":"low","categories":cls,"actions":["allow"],"rationale":"fast models"}
    judge = llm_judge(content, context)
    merged = fuse(cls, judge)  # calibrated fusion
    actions = decide(merged)   # allow/block/rewrite/review
    return {"risk":risk,"categories":merged,"actions":actions,"rationale":"fusion"}


def postprocess(action:list, content:str) -> str:
    if 'rewrite' in action:
        return safe_rewriter(content, POLICY)
    return content
Practical tips and pitfalls
- Separate intent from content. For example, discussing bomb history ≠ constructing a bomb. Encode “allowed assistance” rules.
- Prefer “safe‑complete” over bare refusals to reduce churn and recidivism.
- Calibrate per‑market: cultural context changes thresholds and examples.
- Track model drift. Re‑evaluate safety sets after model or data updates.
- Build explainer text for user messages and for reviewer rationales.
- Test with real adversaries: run bounty‑style red teaming and log novel attacks.
Governance and transparency
- Maintain a public‑facing safety summary, model cards, and change logs.
- Establish a safety review board; require sign‑off for policy or threshold changes.
- Use playbooks for incidents; rehearse with tabletop exercises.
Checklist
- Clear, testable policy with examples and counter‑examples
- Multilayer pipeline: rules → classifiers → LLM‑judge → human review
- Safe‑completion patterns and tool/retrieval gating
- Calibrated thresholds, multilingual coverage, and fairness audits
- Robust logging, redaction, and incident response
- Continuous red teaming and regression testing
Conclusion
Modern content safety is not a single model—it’s an evolving system. The strongest programs combine precise policies, robust detection and generation controls, human expertise, and continuous evaluation. By layering fast filters, accurate classifiers, LLM reasoning, and thoughtful response design, you can reduce harm while preserving user value and creativity across modalities and languages.
Related Posts
Implementing an AI Content Moderation API: Architecture, Policy, and Code
Design and implement a reliable AI content moderation API: taxonomy, architecture, code, policy config, thresholds, privacy, and evaluation best practices.
LLM Tokenizer Comparison: BPE vs SentencePiece (Unigram and SP‑BPE)
Clear comparison of BPE and SentencePiece tokenizers for LLMs: algorithms, Unicode handling, training, benchmarks, and guidance to choose the right one.
Text-to-SQL: From Natural Language to Reliable Queries
A practical guide to building reliable text-to-SQL systems: architectures, prompts, schema linking, safety, evaluation, and production tips.