Building an AI Anomaly Detection API for Streaming Data: Architecture, Models, and Operations
Design and operate a low-latency AI anomaly detection API for streaming data—architecture, models, thresholds, evaluation, and operations.
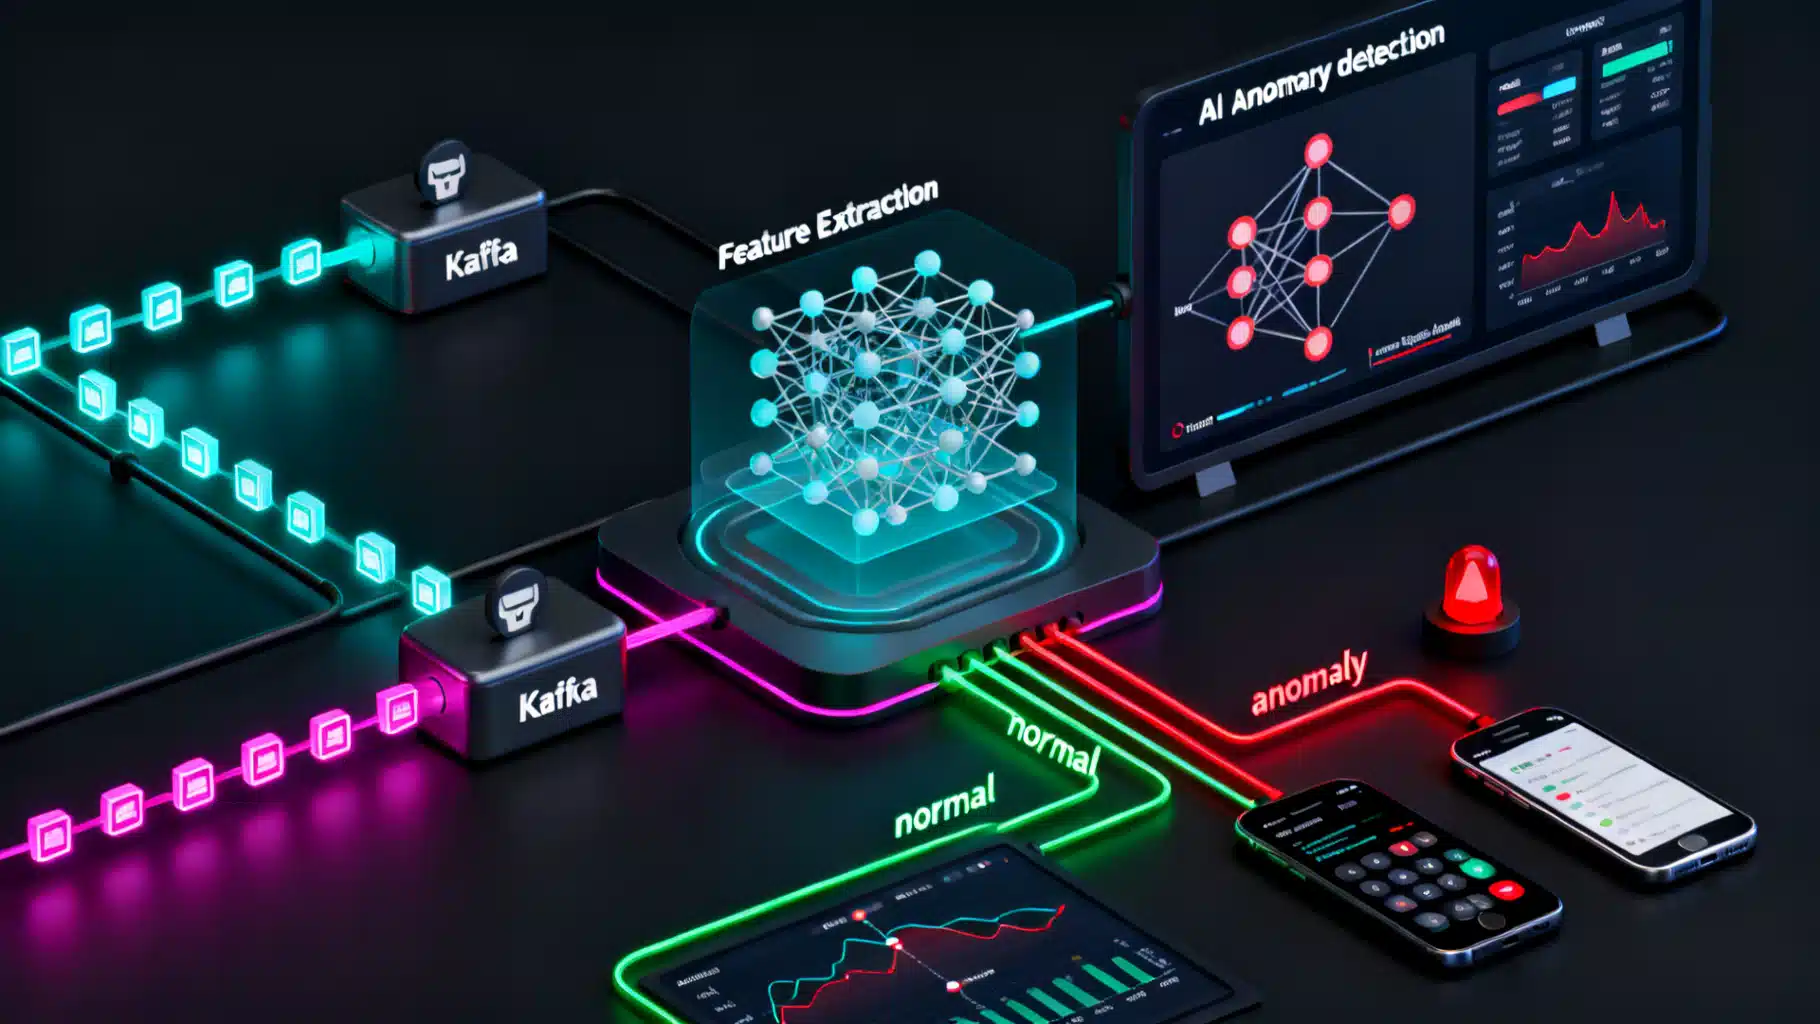
Image used for representation purposes only.
Overview
Anomaly detection on streaming data is a foundation for modern reliability, fraud prevention, security monitoring, and IoT analytics. This article shows how to design, build, and operate an AI-powered anomaly detection API that scores events in milliseconds, adapts to drift, and integrates with production observability and incident workflows.
What counts as an anomaly?
- Point anomalies: a single event deviates strongly (e.g., a sudden latency spike or credit card charge mismatch).
- Contextual anomalies: values are unusual given context such as hour-of-day or user segment (e.g., 500 RPS at 03:00 is abnormal but normal at 18:00).
- Collective anomalies: an unusual pattern over a window (e.g., gradual increase across multiple microservices that together indicate an outage).
Streaming detection must respect ordering, seasonality, and concept drift while meeting strict latency budgets.
Reference architecture
- Ingestion: Kafka/Kinesis/PubSub, webhooks, or device gateways.
- Feature pipeline: online transformations (e.g., rolling stats, sketches), schema validation, enrichment (geo/IP, user segment).
- Online model service: scores events, maintains state (windows, centroids), returns anomaly scores and reason codes.
- Policy engine: thresholds, suppression, routing to on-call, SIEM, or ticketing.
- Feedback + storage: label feedback, event replays, drift monitoring, model updates.
Latency budget example: 10–50 ms P50 scoring, 100 ms P95 end-to-end, with backpressure to handle bursts. Use idempotency keys to deduplicate and exactly-once semantics where possible.
Modeling approaches for streams
Combine fast, robust methods with adaptive thresholds:
- Robust statistics: median/MAD z-scores, EWMA/ EWMVar, Holt–Winters with online updates.
- Change-point detection: CUSUM, Page-Hinkley, Bayesian online change-point detection for level/variance shifts.
- Streaming isolation: Half-Space Trees (a streaming variant of Isolation Forest) for multivariate data.
- One-class learners: online kernel methods, incremental PCA for reconstruction error.
- Autoencoders: lightweight GRU/LSTM or small MLP autoencoders with quantized weights; update via mini-batches or periodic retrains.
- Probabilistic forecasts: quantile forecasts (e.g., p5–p95) and flag if observed is outside bands.
Blend signals via a calibrated anomaly_score in [0,1] and output interpretable reason codes (e.g., “ewma_spike”, “changepoint”, “recon_error”).
Feature engineering for real time
- Time/context: hour, day-of-week, holiday, region; encode cyclic time with sin/cos.
- Rolling features: EWM mean/var, rolling min/max, counts in sliding windows.
- Cross-entity aggregation: per-user, per-service, per-tenant statistics with bounded memory via sketches.
- Cardinality control: HyperLogLog for distincts, Count–Min Sketch for frequencies.
- Normalization: per-entity robust scaling maintained online.
Streaming semantics: windows and ordering
- Windows: sliding (overlap), tumbling (disjoint), and session (gap-based). Choose based on use case: security (short, sliding), finance (event-driven), IoT (sensor-aligned).
- Ordering: maintain event_time vs processing_time; use watermarks to handle late data. Define how long you’ll wait before finalizing a score for a window.
- Delivery: aim for at-least-once with idempotency; where critical, add transaction logs for effectively-once.
API design principles
- Protocols: HTTPS (sync), Server‑Sent Events or WebSocket (bidirectional streaming), gRPC (low-latency, strongly typed).
- Authentication: OAuth2 client credentials or mTLS. Rotate keys and support per-tenant RBAC scopes.
- Versioning: URI or header-based (e.g., X-API-Version: 2026‑09‑01). Support schema evolution with additive fields and defaulting.
- Idempotency: Idempotency-Key header with a 24–72h cache.
- Observability: return correlation_id; emit metrics for latency, error rate, drift, and alert volume.
Example request and response (HTTP JSON)
POST /v1/score HTTP/1.1
Authorization: Bearer <token>
Content-Type: application/json
Idempotency-Key: 9d3e7c7a-0d3e-4d7a-a2f1-42ab

{
  "event_time": "2026-09-26T14:36:21Z",
  "entity_id": "svc:checkout",
  "features": {
    "latency_ms": 482,
    "error_rate": 0.08,
    "rps": 1200,
    "region": "us-east-1",
    "hour": 14
  },
  "tags": {"deploy_sha": "a1b2c3"}
}
{
  "correlation_id": "c-01HEW7...",
  "anomaly_score": 0.93,
  "label": "anomalous",
  "reasons": [
    {"type": "ewma_spike", "feature": "latency_ms", "z": 4.2},
    {"type": "changepoint", "feature": "error_rate"}
  ],
  "dynamic_threshold": 0.85,
  "window": {"size_s": 300, "watermark_lag_s": 30},
  "model_version": "hst-2026-09-15",
  "explanations": {"shap_top": ["latency_ms", "error_rate", "rps"]}
}
Streaming with WebSocket (JSON Lines)
Client → ws://api.example.com/v1/stream/score
{"entity_id":"device-882","latency_ms":38,"rps":12,"ts":"2026-09-26T14:36:21Z"}
{"entity_id":"device-882","latency_ms":66,"rps":21,"ts":"2026-09-26T14:36:22Z"}
...
Server ← {"correlation_id":"c-...","anomaly_score":0.11}
Server ← {"correlation_id":"c-...","anomaly_score":0.91,"label":"anomalous"}
Example client code
Curl (quick smoke test)
curl -sS -X POST https://api.example.com/v1/score \
  -H "Authorization: Bearer $TOKEN" \
  -H "Content-Type: application/json" \
  -H "Idempotency-Key: $(uuidgen)" \
  -d '{
    "event_time": "2026-09-26T14:36:21Z",
    "entity_id": "acct:123",
    "features": {"amount": 9999.99, "merchant_mcc": 5732, "hour": 3}
  }'
Python (requests + streaming)
import json, requests, uuid

payload = {
    "event_time": "2026-09-26T14:36:21Z",
    "entity_id": "svc:billing",
    "features": {"latency_ms": 220, "rps": 400, "error_rate": 0.03, "hour": 14}
}

r = requests.post(
    "https://api.example.com/v1/score",
    headers={
        "Authorization": f"Bearer {TOKEN}",
        "Content-Type": "application/json",
        "Idempotency-Key": str(uuid.uuid4())
    },
    data=json.dumps(payload), timeout=0.2
)
print(r.json())
Node.js (WebSocket stream)
import WebSocket from 'ws';

const ws = new WebSocket('wss://api.example.com/v1/stream/score', {
  headers: { Authorization: `Bearer ${process.env.TOKEN}` }
});

ws.on('open', () => {
  setInterval(() => {
    const msg = { entity_id: 'sensor-9', ts: new Date().toISOString(), temp_c: 78.2 };
    ws.send(JSON.stringify(msg));
  }, 1000);
});

ws.on('message', (buf) => {
  const res = JSON.parse(buf.toString());
  if (res.anomaly_score > 0.9) console.warn('ALERT', res);
});
Thresholds and policy
Avoid fixed thresholds. Use:
- Dynamic baselines per entity, per hour-of-week.
- Quantile bands (e.g., alert when value < p1 or > p99 given context).
- Score calibration via Platt scaling or isotonic regression to map raw scores to risk probabilities.
- Multi-signal voting and hysteresis to suppress flapping.
- Cooldowns and maintenance windows (deploys, migrations) to reduce false positives.
Evaluation and validation
You need both offline and online evaluation:
- Offline replay: sample historical streams and compute precision, recall, PR‑AUC, and expected alerts/day per team.
- Online shadow: score in parallel without alerting to measure drift and stability.
- Canary: promote by tenant or service; track MTTD (mean time to detect) and MTTA (acknowledge) alongside FP rate.
- Cost-aware metrics: assign costs to false positives/negatives and optimize expected cost.
- Drift monitoring: track population stability index (PSI), feature missingness, and concept drift (e.g., ADWIN detectors).
KPIs to publish weekly:
- Alert precision (7‑day rolling)
- Alerts per 1,000 events
- Median detection latency
- Top 5 reason codes and noisy entities
Reliability and performance
- Backpressure: use bounded queues; shed load with 429 + retry-after when downstream lags.
- State management: keep model state in memory with periodic checkpoints (e.g., every N events or M seconds) to durable storage.
- Warm-up: return label: “warming” when insufficient history exists; optionally default to conservative thresholds.
- Caching: memoize per-entity contexts; expire on inactivity.
- Parallelism: shard by entity_id hash to keep order and local state affinity.
- Batching: micro-batch (e.g., 10–100 events) for deep models when latency allows.
Explainability and root cause hints
- Provide top contributing features (e.g., SHAP values, gradient-based attributions) with caps to keep payload small.
- Add correlation hints: “co-occurs with deploy_sha=a1b2c3 in 83% of recent anomalies.”
- Link alerts to dashboards and traces via correlation_id.
Security, privacy, and compliance
- Minimize PII: hash or tokenize identifiers; avoid raw payloads in logs.
- Encryption in transit (TLS 1.2+) and at rest (KMS-managed keys).
- RBAC and tenant isolation; per-tenant rate limits and budgets.
- Audit trails: sign critical responses; keep immutable logs for 1–7 years per policy.
- Data retention: stream features only; purge raw events quickly unless mandated.
Cost control and scalability
- Feature thrift: compute only features that move precision/recall.
- Approximate data structures: sketches, reservoir sampling for baselines.
- Model compression: quantization, distillation, or small HST ensembles.
- Autoscaling: scale on queue depth and P95 latency, not CPU alone.
- Storage hygiene: compact checkpoints; prune stale per-entity states.
Testing and operations
- Load tests with realistic burstiness and skewed keys.
- Chaos experiments: kill pods/instances; verify state restore and at-least-once guarantees.
- Replay drills: reproduce known incidents to confirm detection remains intact after updates.
- Runbooks: for each alert class, define triage steps, suppression criteria, and rollback plans.
Minimal server outline (Python‑style pseudocode)
class AnomalyService:
    def __init__(self, model, state_store):
        self.model = model
        self.state = state_store

    def score(self, event):
        ctx = self.state.get(event.entity_id)
        feats = featurize(event, ctx)
        score, reasons = self.model.score_online(feats, ctx)
        thresh = dynamic_threshold(event.entity_id, event.hour)
        label = 'anomalous' if score >= thresh else 'normal'
        self.state.update(event.entity_id, feats)
        return {
            'anomaly_score': score,
            'label': label,
            'reasons': reasons,
            'dynamic_threshold': thresh
        }
Implementation checklist
- Define entities, windows, and drift policy per domain.
- Choose protocol: HTTP for sync, WebSocket/gRPC for low-latency streams.
- Implement idempotency, versioning, and observability from day one.
- Start with robust stats + change-point; add ML only where it lifts precision/recall.
- Calibrate thresholds with cost-aware evaluation.
- Build feedback loops and runbooks before company-wide rollout.
Conclusion
A production-grade anomaly detection API for streaming data is more than a model. It is an end-to-end system that transforms raw events into timely, actionable signals with clear explanations and tight operational hooks. Start simple, measure relentlessly, and iterate on thresholds, features, and policies while keeping latency, cost, and privacy under control.
Related Posts
From Prototype to Production: Deploying Autonomous AI Agents Safely and at Scale
A practical blueprint for deploying autonomous AI agents to production—architecture, safety, reliability, evals, cost control, and ops patterns.
REST API Multitenancy Patterns: Isolation, Routing, and Scale
A practical guide to REST API multitenancy patterns: routing, isolation, auth, quotas, caching, observability, and deployment—plus concise code examples.
Designing REST APIs with Partial Response Field Selection (fields, select, $select)
Design and implement REST API partial responses for speed and safety—syntax options, caching, security, and implementation patterns with examples.