Designing API Event-Driven Architectures with Apache Kafka: A Practical Guide
A practical, end-to-end guide to building API event-driven architectures with Apache Kafka—design, patterns, reliability, security, and operations.
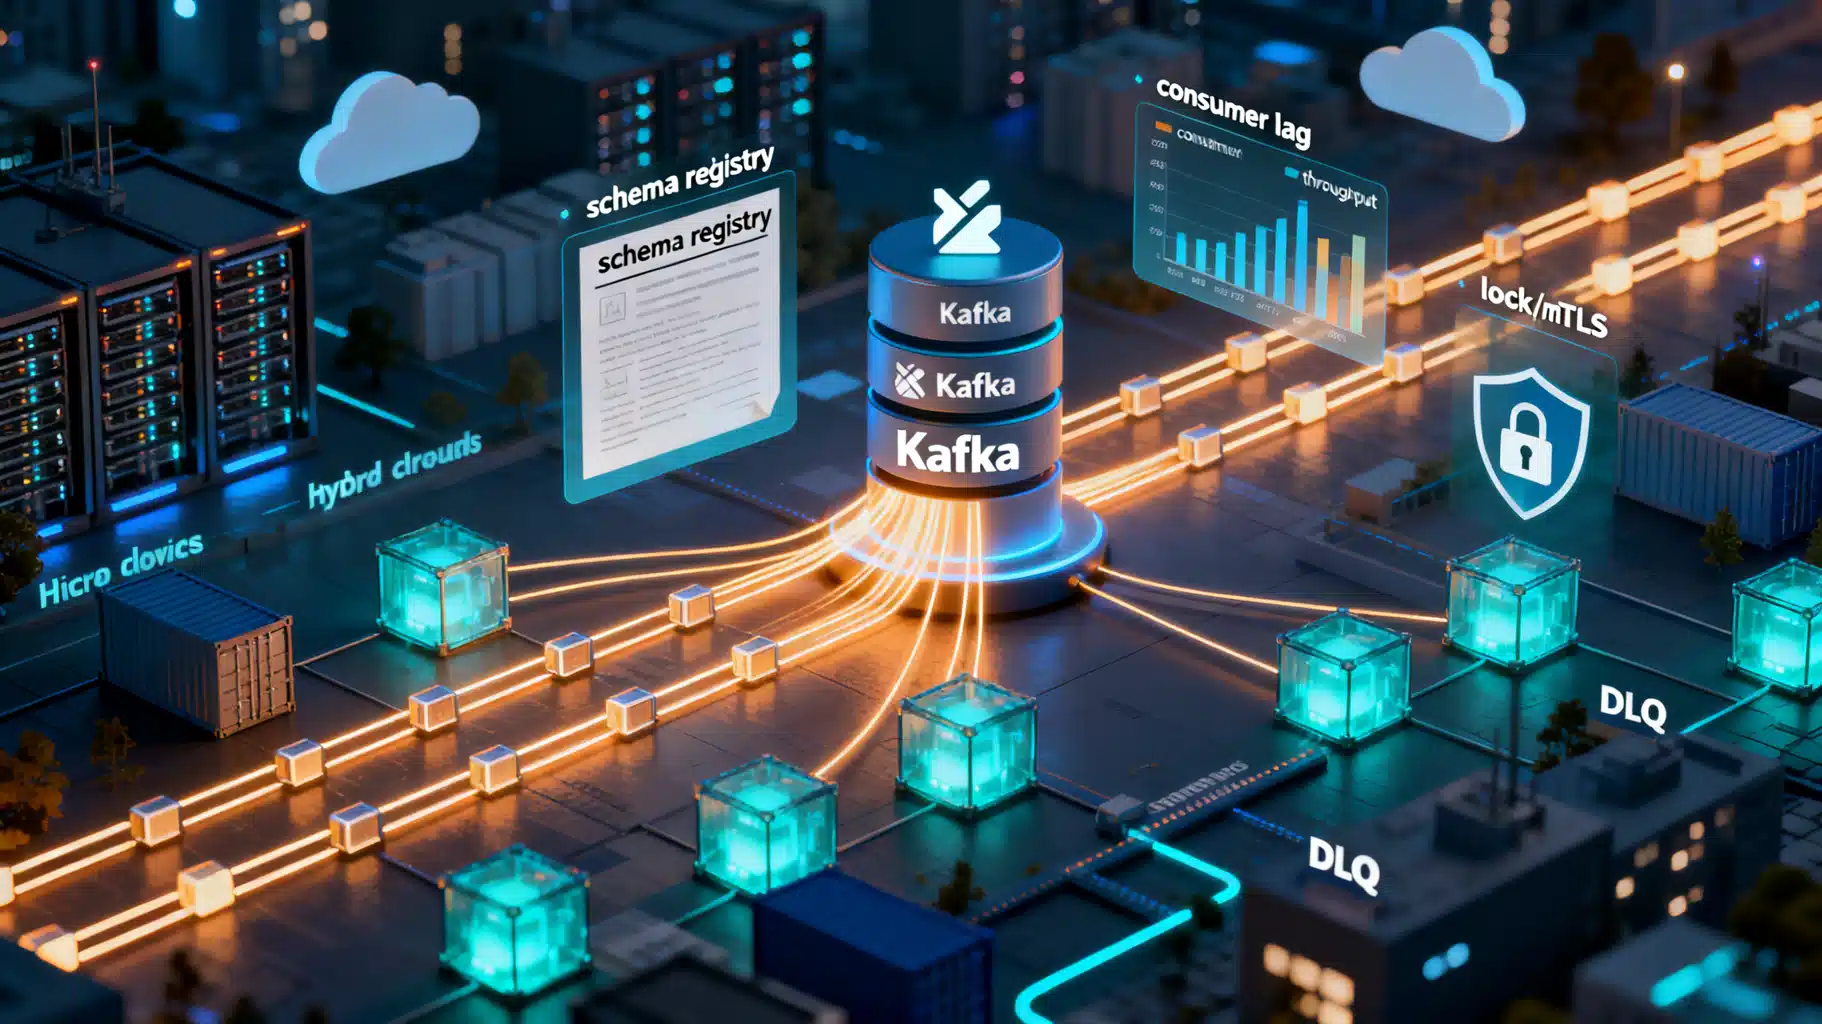
Image used for representation purposes only.
Why event-driven APIs, and why Kafka?
APIs have long been synchronous request/response endpoints. That model works for CRUD and quick queries, but it strains when workloads need loose coupling, resilience to spikes, real‑time updates, and independent evolution of services. Event-driven architecture (EDA) treats business changes as immutable events that services publish and react to. Apache Kafka is a natural backbone for EDA because it offers durable logs, horizontal scalability via partitions, consumer groups for parallelism, and strong ordering guarantees per key. Combined with schema governance and modern tooling, Kafka turns APIs from “pull data when you need it” into “subscribe to changes as they happen.”
Core Kafka concepts for API architects
- Topic: An append-only log of events. Split into partitions for parallelism. Ordering is guaranteed within a partition.
- Key: Determines partition placement and ordering affinity. Choose keys that align with your business invariants (e.g., customerId, orderId).
- Producer/Consumer: Writers and readers of topics. Consumer groups coordinate work distribution and offset management.
- Retention: Time- or size-based. Long retention enables replays and new projections; compaction keeps the latest value per key.
- Exactly-once semantics (EOS): With idempotent producers and transactions, Kafka can provide end-to-end exactly-once processing with Kafka Streams or transactional consumers.
When to use event-driven APIs
Use Kafka-backed APIs when you need:
- Cross-service workflows and eventual consistency (orders, payments, fulfillment).
- Near–real-time data distribution to caches, search indexes, analytics, or ML features.
- Auditability and replays for debugging, forensics, and new consumers.
- Progressive decoupling of a monolith into microservices without breaking synchronous clients.
Prefer conventional REST/gRPC when:
- You need strict request/response with low-latency reads and no eventual consistency.
- There is no business event to publish and no downstream subscribers.
Designing event contracts and governance
Treat events like public API surfaces.
- Event types: Domain events (OrderPlaced), state transfer events (CustomerUpdated), and integration events (PaymentAuthorized). Keep names past-tense and business-centric.
- Schemas: Use Avro or JSON Schema with a registry to manage evolution (backward or full compatibility). Avoid “stringly-typed” payloads.
- Versioning: Prefer additive changes. For breaking changes, publish new topics or new subject versions with compatibility rules.
- Ownership: Each domain team owns its events, schema lifecycle, and SLAs.
- Documentation: AsyncAPI describes channels (topics), messages, and bindings—your event equivalent of OpenAPI.
AsyncAPI example for an Orders domain:
asyncapi: 3.0.0
info:
  title: Orders Events
  version: 1.0.0
channels:
  orders.v1:
    address: orders.events.v1
    messages:
      OrderPlaced:
        payload:
          $ref: '#/components/schemas/OrderPlaced'
components:
  schemas:
    OrderPlaced:
      type: object
      required: [orderId, customerId, total, items, occurredAt]
      properties:
        orderId:
          type: string
        customerId:
          type: string
        total:
          type: number
          format: double
        items:
          type: array
          items:
            type: object
            required: [sku, qty, price]
            properties:
              sku: { type: string }
              qty: { type: integer }
              price: { type: number }
        occurredAt:
          type: string
          format: date-time
Avro schema (compact, binary, evolvable):
{
  "type": "record",
  "name": "OrderPlaced",
  "namespace": "com.acme.orders",
  "fields": [
    {"name": "orderId", "type": "string"},
    {"name": "customerId", "type": "string"},
    {"name": "total", "type": "double"},
    {"name": "items", "type": {"type": "array", "items": {
      "name": "Item", "type": "record", "fields": [
        {"name": "sku", "type": "string"},
        {"name": "qty", "type": "int"},
        {"name": "price", "type": "double"}
      ]
    }}},
    {"name": "occurredAt", "type": {"type": "long", "logicalType": "timestamp-millis"}}
  ]
}
API patterns with Kafka
- Publish/Subscribe: Services publish facts; many subscribers react independently (inventory, billing, notifications).
- Request/Reply over Kafka: Use a correlationId header and a reply-to topic. Useful for async queries and backpressure-friendly RPC.
- Event-Carried State Transfer: Consumers maintain local read models to answer API requests without synchronous hops.
- CQRS: Commands via synchronous APIs; resulting events update projections for reads.
- Sagas: Long-running workflows where each step emits events and compensating actions handle failures.
- Transactional Outbox: Write domain change and an “outbox” row in the same DB transaction; CDC (e.g., Debezium) streams the outbox to Kafka to prevent dual-write bugs.
Outbox table sketch:
CREATE TABLE outbox (
  id UUID PRIMARY KEY,
  aggregate_id TEXT NOT NULL,
  type TEXT NOT NULL,
  payload JSONB NOT NULL,
  occurred_at TIMESTAMPTZ NOT NULL DEFAULT now(),
  published BOOLEAN NOT NULL DEFAULT FALSE
);
Building the pipeline
- Producers: Validate schemas client-side. Set delivery.timeout.ms, acks=all, enable.idempotence=true. Use keys to preserve per-aggregate ordering.
- Consumers: Use consumer groups. Commit offsets after successful processing; for at-least-once semantics, process then commit. For EOS, use transactions.
- Kafka Streams/ksqlDB: Materialize views, join streams/tables, enforce EOS with processing.guarantee=exactly_once_v2.
- Kafka Connect: Source/sink connectors to databases, object stores, search, etc. Debezium for CDC and outbox.
Transactional producer example (Java):
Properties p = new Properties();
p.put("bootstrap.servers", "kafka:9092");
p.put("key.serializer", "org.apache.kafka.common.serialization.StringSerializer");
p.put("value.serializer", "io.confluent.kafka.serializers.KafkaAvroSerializer");
p.put("enable.idempotence", "true");
p.put("acks", "all");
p.put("max.in.flight.requests.per.connection", "5");
p.put("transactional.id", "orders-svc-tx-1");

try (Producer<String, OrderPlaced> producer = new KafkaProducer<>(p)) {
  producer.initTransactions();
  producer.beginTransaction();
  ProducerRecord<String, OrderPlaced> rec = new ProducerRecord<>(
      "orders.events.v1", order.getId(), toAvro(order));
  producer.send(rec);
  // Optionally send to outbox-confirmation topic within same tx
  producer.commitTransaction();
} catch (ProducerFencedException e) {
  // Recover transactional.id or failover
}
Node.js consumer with group and basic retry:
const { Kafka } = require('kafkajs');
const kafka = new Kafka({ clientId: 'billing-svc', brokers: ['kafka:9092'] });
const consumer = kafka.consumer({ groupId: 'billing-svc-v1' });

(async () => {
  await consumer.connect();
  await consumer.subscribe({ topic: 'orders.events.v1', fromBeginning: false });

  await consumer.run({
    eachMessage: async ({ message, partition }) => {
      const key = message.key?.toString();
      const evt = JSON.parse(message.value.toString());
      try {
        await chargeCustomer(evt);
      } catch (err) {
        // produce to DLQ with headers for triage
        await produceDLQ(evt, err, partition);
      }
    }
  });
})();
Debezium connector (outbox) snippet:
{
  "name": "outbox-connector",
  "config": {
    "connector.class": "io.debezium.connector.postgresql.PostgresConnector",
    "database.hostname": "db",
    "database.port": "5432",
    "database.user": "debezium",
    "database.password": "***",
    "database.dbname": "orders",
    "tombstones.on.delete": "false",
    "table.include.list": "public.outbox",
    "transforms": "route",
    "transforms.route.type": "io.debezium.transforms.outbox.EventRouter",
    "transforms.route.route.by.field": "type",
    "transforms.route.route.topic.replacement": "${r}.v1",
    "value.converter": "org.apache.kafka.connect.json.JsonConverter",
    "value.converter.schemas.enable": "false"
  }
}
Reliability and correctness
- Ordering: Kafka guarantees order per partition. Choose a stable key (e.g., orderId) to keep related events together. Avoid hot keys by sharding (e.g., hash(customerId) % N) when a single key gets too hot.
- Delivery semantics: Prefer at-least-once with idempotent handlers (natural for many business ops). Use EOS with transactions when duplicates are intolerable.
- Retries and DLQs: Use bounded retries with exponential backoff. Send failures to a dead-letter topic with headers: error, stack, original-topic, partition, offset, processing-timestamp.
- Idempotency: Deduplicate by natural keys, idempotency keys, or store processed offset per key. For mutable side-effects (emails, payments), maintain a “sent” or “charged” ledger.
- Backpressure: Consumers should scale horizontally by adding group members; tune max.poll.interval.ms and max.partition.fetch.bytes. Consider pausing consumption while downstream is slow.
Security and compliance
- Transport: TLS everywhere; verify certificates. Use mTLS for service identity.
- AuthN/Z: SASL/SCRAM or OAuth/OIDC with short-lived tokens; enforce ACLs per topic, prefixed by team namespaces.
- Encryption at rest: Broker-level or storage-level encryption. Avoid sensitive PII in payloads; tokenize or reference via lookup keys.
- Governance: Tag topics with data classification. Apply retention and compaction policies that match classification and regulatory needs. Log access, produce/consume audits.
Observability and SLOs
- Golden signals: Produce/consume rates, end-to-end latency, consumer lag, commit rate, DLQ rate.
- Tracing: Propagate trace context (W3C traceparent) via headers. Correlate events to synchronous API requests.
- SLOs: Example targets—p99 end-to-end latency under 2 seconds; consumer lag < 30 seconds for 99.9% of intervals; DLQ rate < 0.1% of messages.
- Alerting: On stalled partitions, rebalance storms, rising lag, storage nearing limits, broker ISR shrink, controller changes.
Capacity planning and partitioning
A quick, back-of-the-envelope approach:
- Throughput: required_msgs_per_sec = peak_rps × average_events_per_request.
- Partition count: partitions ≈ required_msgs_per_sec / target_msgs_per_partition_per_sec.
- Keep per-partition load under ~5–10k msgs/sec for comfortable margins.
- Storage: retention_bytes ≈ incoming_bytes_per_sec × retention_seconds × replication_factor.
- Replication: set replication.factor=3 for production; min.insync.replicas=2 with acks=all to survive broker loss.
Start slightly above your estimate; repartitioning later is possible but involves migration to a new topic.
Deployment options
- Managed Kafka: Confluent Cloud, Amazon MSK, Azure Event Hubs for Kafka API. Reduces ops toil and offers tiered storage, ACLs, observability, and governance.
- Self-managed: Kubernetes with Strimzi or bare-metal. Ensure correct JVM tuning, storage (NVMe), network, and Zookeeper/KIP-500 (KRaft) mode alignment depending on Kafka version.
- Alternatives with Kafka API: Redpanda (single-binary, low latency) can simplify ops and still support Kafka clients.
Integrating synchronous APIs with Kafka
- API Gateway → Producer: After a POST /orders, publish OrderPlaced. If synchronous confirmation is needed, return 201 Created immediately and let subscribers act; or block on a specific reply topic with timeout for a quasi-sync flow.
- Webhooks and WebSockets: Power them from Kafka topics to fan-out to external clients at scale while keeping your core EDA clean.
- Read models: Populate caches (Redis), search indexes (Elasticsearch), and reporting stores (OLAP) via Kafka Connect or Streams; route your GET endpoints to these projections for fast reads.
Migration path from REST to EDA
- Identify domain events already implicit in your workflows.
- Introduce an outbox in the monolith and publish integration events.
- Carve out a read model first (low risk), then move write-side responsibilities to independent services.
- Establish schema registry and governance early; treat topics as contracts.
- Incrementally replace synchronous integrations with subscriptions.
Testing and quality
- Contract tests: Validate producers against schemas and consumers against fixtures. Fail the pipeline on breaking changes.
- Integration tests: Testcontainers spins ephemeral Kafka, Schema Registry, and connectors in CI.
- Replay tests: Rehydrate from retained topics to verify deterministic outcomes after code changes.
- Chaos and failure drills: Kill consumers, partition networks, fill disks; confirm SLOs and recovery behaviors.
Common pitfalls and how to avoid them
- Overloading a single topic with unrelated events: model per-aggregate or per-domain topics with clear ownership.
- Ignoring keys: without a stable key, ordering assumptions break and joins become unreliable.
- Mixing commands with events: commands are requests (imperative), events are facts (declarative). Keep them distinct.
- Leaky payloads: don’t embed sensitive data or giant blobs; store references and fetch on demand.
- Endless retries on poison pills: cap retries and route to DLQ with rich context.
- No retention strategy: pick time/size/compaction policies deliberately; document them.
A minimal checklist
- Topics defined with owners, retention, and compatibility rules.
- Schemas in registry, AsyncAPI published.
- Producers idempotent; consumers idempotent or transactional as needed.
- DLQ and retry policies in place; observability dashboards live.
- Security: TLS/mTLS, ACLs, secrets rotation.
- Capacity: partitions sized to peak; SLOs and alerts defined.
Conclusion
API event-driven architecture with Kafka lets teams scale independently, react in real time, and build resilient systems. Success comes from disciplined event design, explicit contracts, sound reliability patterns, and strong observability. Start small—publish the first well-governed event, wire one consumer, measure, and iterate. Within a few increments, your API surface will evolve from synchronous endpoints to a rich, reactive platform that compounds value across your organization.
Related Posts
Event Sourcing for API Microservices: A Practical Guide
A practical, end-to-end guide to using event sourcing in API-based microservices, with design tips, code snippets, and operational best practices.
gRPC Streaming API Tutorial: Server, Client, and Bidirectional Patterns with Go and Python
Hands-on gRPC streaming tutorial: server, client, and bidirectional streams with Go and Python, plus proto design, flow control, deadlines, security, and testing.
Designing a REST–GraphQL Hybrid Architecture: Patterns, Trade‑offs, and Playbook
Design a pragmatic REST–GraphQL hybrid: patterns, trade‑offs, caching, security, federation, and migration steps to ship faster without breaking what works.